Chapter 6: Specification Gaming
Learning from feedback
Learning from feedback, Markov Grey, Charbel-Raphaël Segerie
Training an AI with human feedback, like thumbs-up or thumbs-down, can help shape its behavior. But the AI can learn to manipulate or fool its human evaluators, or become sycophantic to get more rewards.
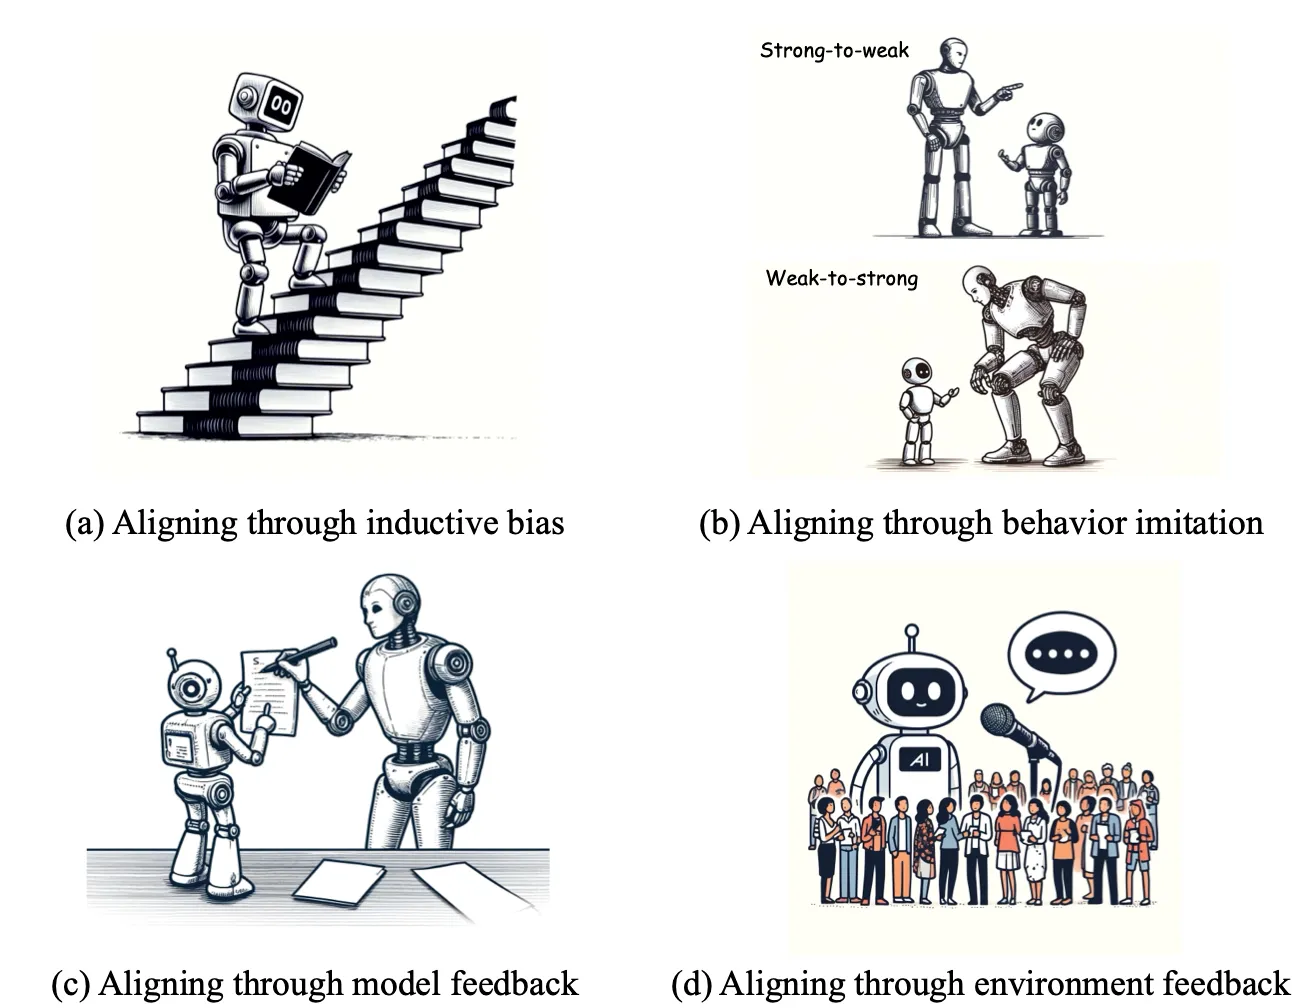
Figure 6.12: Illustration of different ways being pursued of achieving alignment. (Cao et al., 2024)
This section discusses yet more attempts to address the reward misspecification problem. At times, the intended behavior is so intricate that demonstration-based learning becomes untenable. An alternative approach is to offer feedback to the agent instead of providing either manually specified reward functions or even expert demonstrations. This section delves into feedback-based strategies such as Reward Modeling, Reinforcement Learning from Human Feedback (RLHF) and Reinforcement Learning from AI Feedback (RLAIF), also known as Reinforcement Learning from Constitutional AI (RLCAI) or simply Constitutional AI.
Reward Modeling
Video: Training AI Without Writing A Reward Function, with Reward Modelling, Robert Miles AI Safety
Hi. What is technology? Don't skip ahead, I promise I'm going somewhere with this. So you could have some kind of definition from a dictionary that's like, technology is machinery and equipment made using scientific knowledge, something like that. But where are the boundaries of the category? What counts, for example, pair of scissors, technology? I think most people would say no, although it does meet the definition. Perhaps scissors used to be technology, but now I think they're too simple, they're too well understood. I think once we've really nailed something down and figured out all of the details, people stop thinking of it as technology. I think in order to be technology, something has to be complex and unpredictable, maybe even unreliable. YouTube, for example, is definitely technology, as is the device you're watching this on. Okay, why does this matter? I guess part of my point is the exact definitions are really difficult, and this generally isn't much of a problem, because language doesn't really work by exact definitions. Maybe it's hard to specify exactly what we mean when we use a word like technology, but to paraphrase something from the US Supreme Court, you know it when you see it, and that's good enough for most uses. The reason I bring this up is sometimes people ask me about my definition of artificial intelligence, and actually I think that's pretty similar. You could say that AI is about trying to get machines to carry out human cognitive tasks, but then arithmetic is a cognitive task. Does that make a calculator artificial intelligence? Sorting a list is a cognitive task, I don't think most people would call that AI. Playing a perfect game of noughts and crosses used to be considered AI, but I don't think we'd call it that these days. So to me, AI is about making machines do cognitive tasks that we didn't think they could do. Maybe it's because it's about making machines do human cognitive tasks, and once machines can do something, we no longer think of it as a human cognitive task. This means that the goalposts are always moving for artificial intelligence. Some people have complained about that, but I think it's pretty reasonable to have that as part of the definition. So that means that the goal of AI research is to continue to expand the range of tasks that computers can handle so they can keep surprising us. It used to be that AI research was all about figuring out and formalizing things so that we could write programs to do them, things like arithmetic, sorting lists, and playing noughts and crosses. These are all in the class of problems that you might call things we can specify well enough to write programs that do them, and for a long time that was all that we could do, that was the only type of problem we could tackle. But for a lot of problems that approach is really, really hard. Like, consider how would you write a program that takes an image of a handwritten digit and determines what digit it is. You can formalize the process and try to write a program, it's actually kind of a fun exercise if you want to get to grips with the old school computer vision and image processing techniques. And once you've written that program, you can test it using the MNIST dataset, which is a giant collection of correctly labeled small images of digits. What you'll find is if you do well, then this thing will kind of work, but even the best programs written this way don't work that well, they're not really reliable enough to actually use, someone is always going to come along with a really blunt pencil and ruin your program's accuracy. And this is still a pretty easy problem. I mean, what if you wanted to do something like letters as well as numbers? Now you have to differentiate between oh and zero, and one and I, and a lowercase L. Forget about it, it's never going to work. And even that is a relatively simple problem. What if you're trying to do something like differentiating pictures of cats from pictures of dogs? This whole approach is just not going to work for that. But there is a fact that we can exploit, which is that it's a lot easier to evaluate a solution than to generate a solution for a lot of these problems. I've talked about this before, I couldn't generate a good rocket design myself, but I can tell you that this one needs work. It's easier to write a program to evaluate an output than to write one to produce that output. So maybe it's too hard to write a program that performs the task of identifying handwritten numbers, but it's pretty easy to write a program that evaluates how well a given program does at that task, as long as you have a load of correctly labeled examples. You just keep giving it labeled examples from the dataset and you see how many it gets right. In the same way, maybe you can't write a program that plays an Atari game well, but you can easily write a program that tells you how well you're doing, you just read off the score. And this is where machine learning comes in. It gives you ways to take a program for evaluating solutions and use it to create good solutions. All you need is a dataset with a load of labeled examples, or a game with a score, or some other way of programmatically evaluating the outputs, and you can train a system that carries out the task. There's a sense in which this is a new programming paradigm, instead of writing the program itself, you write the reward function or the loss function or whatever, and the training process finds you a set of parameters for your network that perform well according to that function. If you squint, the training process is sort of like a compiler, it's taking code you've written and turning it into an executable that actually performs the task. So in this way, machine learning expands the class of tasks that machines can start to perform, it's no longer just tasks that you can write programs to do, but tasks that you can write programs to evaluate. But if this is a form of programming, it's a very difficult one. Anyone who has programmed in C or C++ will tell you that the two scariest words you can see in a specification are "undefined behavior." So, how many folks are a little bit afraid of undefined behavior in their source code? Everybody. And machine learning as a programming paradigm is pretty much entirely undefined behavior, and as a consequence, programs created in this way tend to have a lot of quite serious bugs. And these are things that I've talked about before on the channel, for example, reward gaming, where there's some subtle difference between the reward function you wrote and the actual reward function that you kind of meant to write, and an agent will find ways to exploit that difference to get high reward, to find things it can do which the reward function you wrote gives a high reward to, but the reward function you meant to write wouldn't have. Or the problem of side effects, where you aren't able to specify in the reward function everything that you care about, and the agent will assume that anything not mentioned in the reward function is of zero value, which can lead to it having large negative side effects. There are a bunch more of these specification problems, and in general this way of creating programs is a safety nightmare. But also, it still doesn't allow machines to do all of the tasks that we might want them to do. A lot of tasks are just too complex and too poorly defined to write good evaluation functions for. For example, if you have a robot and you want it to scramble you an egg, how do you write a function which takes input from the robot's senses and returns how well the robot is doing at scrambling an egg? That's a very difficult problem. Even something simple like getting a simulated robot to do a backflip, it's actually pretty hard to specify what we want. Well, normal reinforcement learning looks like this. You have an agent and an environment, the agent takes actions in the environment, and the environment produces observations and rewards. The rewards are calculated by the reward function, that's where you program in what you want the agent to do. So some researchers tried this with the backflip task. They spent a couple of hours writing a reward function, it looks like this, and the result of training the agent with this reward function looks like this. I guess that's basically a backflip, I've seen better. Something like evaluating a backflip is very hard to specify, but it's not actually hard to do, like it's easy to tell if something is doing a backflip just by looking at it, it's just hard to write a program that does that. So what if you just directly put yourself in there, if you just play the part of the reward function, every time step you look at the state and you give the agent a number for how well you think it's doing at backflipping. People have tried that kind of approach, but it has a bunch of problems. The main one is these systems generally need to spend huge amounts of time interacting with the environment in order to learn even simple things, so you're going to be sitting there saying, "No, that's not a backflip. No, that's not a backflip either. That was closer. Nope, that's worse again," and you're gonna do this for hundreds of hours. Nobody has time for that. So what can we do? Well, you may notice that this problem is a little bit like identifying handwritten digits, isn't it? We can't figure out how to write a program to do it, and it's too time consuming to do it ourselves, so why not take the approach that people take with handwritten numbers, why not learn our reward function? But it's not quite as simple as it sounds, backflips are harder than handwritten digits, in part because, where are you going to get your data from? For digits we have this dataset MNIST, we have this giant collection of correctly labeled images, we built that by having humans write lots of numbers, scanning them, and then labeling the images. We need humans to do the thing, to provide examples to learn from, we need demonstrations. Now, if you have good demonstrations of an agent performing a task, you can do things like imitation learning and inverse reinforcement learning, which are pretty cool, but they're a subject for a later video. But with backflips we don't have that, I'm not even sure if I can do a backflip. And that wouldn't help. Wait, really, I don't have to do it? No, we don't need a recording of a human backflipping, we need one of this robot backflipping. Right, their physiology is different. But I don't think I could puppeteer the simulated robot to backflip either, that would be like playing co-op on nightmare mode. So we can't demonstrate the task, so what do we do? Well, we go back to the Supreme Court, exactly defining a backflip is hard, doing it isn't actually that hard, but I know a backflip when I see one. So we need a setup that learns a good reward function without demonstrations, just by using human feedback, without requiring too much of the human's time. And that's what this paper does, it's called "Deep Reinforcement Learning from Human Preferences," and it's actually a collaboration between OpenAI and DeepMind. The paper documents a system that works by reward modeling, if you give it an hour of feedback, it does this, that looks a lot better than two hours of reward function writing. So how does reward modeling work? Well, let's go back to the diagram. In reward modeling, instead of the human writing the reward function, or just being the reward function, we instead replace the reward function with a reward model, implemented as a neural network. So the agent interacts with the environment in the normal way, except the rewards it's getting are coming from the reward model. The reward model behaves just like a regular reward function, in that it gets observations from the environment and gives rewards, but the way it decides those rewards is with a neural network, which is trying to predict what reward a human would give. Okay, how does the reward model learn what reward a human would give? Well, the human provides it with feedback. So the way that works is, the agent is interacting with the environment, trying to learn, and then the system will extract two short clips of the agent flailing about, just a second or two, and it presents those two clips to the human, and the human decides which they liked better, which one is more backflipping. And the reward model then uses that feedback in basically the standard supervised learning way, it tries to find a reward function such that in situations where the human prefers the left clip to the right clip, the reward function gives more reward to the agent in the left clip than the right clip, and vice versa. So which clip gets more reward from the reward model ends up being a good predictor of which clip the human would prefer, which should mean that the reward model ends up being very similar to the reward function the human really wants. But the thing I like about this is the whole thing is happening asynchronously, it's all going on at the same time. The agent isn't waiting for the human, it's constantly interacting with the environment, getting rewards from the reward model, and trying to learn, at many times faster than real time. And the reward model isn't waiting either, it's continually training on all of the feedback that it's got so far, when it gets new feedback it just adds that to the dataset and keeps on training. This means the system is actually training for tens or hundreds of seconds for each second of human time used. So the human is presented with a pair of clips and gives feedback, which takes just a few seconds to do, and while that's happening the reward model is updating to better reflect their previous feedback, and the agent is spending several minutes of subjective time learning and improving using that slightly improved reward model. So by the time the human is done giving feedback on those clips and it's time for the next pair, the agent has had time to improve, so the next pair of clips will have new, hopefully better, behavior for the human to evaluate. This means that it's able to use the human's time quite efficiently. Now, to further improve that efficiency, the system doesn't just choose the clips randomly, it tries to select clips where the reward model is uncertain about what the reward should be, like there's no point asking for feedback if you're already pretty sure you know what the answer is, right? So this means that the user is most likely to see clips from unusual moments, when the agent has worked out something new and the reward model doesn't know what to make of it. That maximizes the value of the information provided by the human, which improves the speed the system can learn. So what about the usual reinforcement learning safety problems, like negative side effects and reward gaming? You might think that if you use a neural network for your reward signal, it would be very vulnerable to things like reward gaming, since the reward model is just an approximation, and we know that neural networks are very vulnerable to adversarial examples and so on. And it's true that if you stop updating the reward model, the agent will quickly learn to exploit it, to find strategies that the reward model scores highly but the true reward doesn't. But the constant updating of the reward model actually provides pretty good protection against this, and the way that the clips are chosen is part of that. If the agent discovers some crazy new illegitimate strategy to cheat and get high reward, that's going to involve unusual, novel behavior, which will make the reward model uncertain, so the human will immediately be shown clips of the new behavior. And if it's reward gaming rather than real progress, the human will give feedback saying, "No, that's not what I want," the reward model will update on that feedback and become more accurate, and the agent will no longer be able to use that reward gaming strategy. So the idea is pretty neat, and it seems to have some safety advantages. How well does it actually work, is it as effective as just programming a reward function? Well, for the backflip, it seems like it definitely is, and it's especially impressive when you note that this is two hours of time to write this reward function, which needs a lot of expertise, compared to under one hour of rating clips, which needs basically no expertise. So this is two hours of expert time versus one hour of novice time. Now they also tried it on the standard MuJoCo simulated robotics tasks that have standard reward functions defined for them, here it tends to do not quite as well as regular reinforcement learning that's just directly given the reward function, but it tends to do almost as well, and sometimes it even does better, which is kind of surprising. They also tried it on Atari games, now for those it needed more feedback because the task is more complex, but again it tended to do almost as well as just providing the correct reward function for several of the games. Also, there's kind of a fun implementation detail here, they had to modify the games to not show the score, otherwise the agent might learn to just read the score off the screen and use that, they wanted to rely on the feedback. So it seems like reward modeling is not much less effective than just providing a reward function, but the headline to me is that they were able to train these agents to do things for which they had no reward function at all, like the backflip. Of course, they also got the cheetah robot to stand on one leg, which is a task I don't think they ever tried to write a reward function for. And in Enduro, which is an Atari game, a racing game, they managed to train the agent using reward modeling to stay level with other cars, even though the game's score rewards you for going fast and overtaking them. And what all this means is that this type of method is again expanding the range of tasks machines can tackle, it's not just tasks we can write programs to do, or tasks we can write programs to evaluate, or even tasks we're able to do ourselves, all that's required is that it's easy to have great outputs, that you know good results when you see them, and that's a lot of tasks. But it's not everything, consider for example a task like writing a novel, sure you can read two novels and say which one you liked more, but this system needed 900 comparisons to learn what a backflip is. Even if we assume that writing a novel is no more complicated than that, does that mean comparing 900 pairs of AI-generated novels? And a lot of tasks are like this, what if we want our machine to run a company, or design something complex like a city's transportation system, or a computer chip? We can't write a program that does it, we can't write a program that evaluates it, we can't reliably do it ourselves enough to make a good dataset, we can't even evaluate it ourselves without taking way too much time and resources. So we're screwed, right? Not necessarily, there are some approaches that might work for these kinds of problems, and we'll talk about them in a later video. I recently realized that my best explanations and ideas tend to come from actual conversations with people, so I've been trying a thing where for each video I first have a couple of video calls with Patreon supporters, where I try sort of running through the idea and seeing what questions people have, and what's not clear, and so on. So I want to say a big thank you to the patrons who helped with this video, you know who you are. I'm especially thanking Jake, Eric, and of course thank you to all of my patrons who make this whole thing possible with their support. Which reminds me, this video is sponsored by nobody. No, I actually turned down a sponsorship offer for this video, and I'll admit I was tempted, because it's a company whose product I've used for like 10 years, and the offer was thousands of pounds, but they wanted me to do this whole 60 second long spiel, and I just thought no, I don't want to waste people's time with that. And I don't have to, because I've got Patreon. So thank you again to all of you, if you like learning about AI safety more than you like learning about mattresses and VPNs, you might want to consider joining those, link in the description. Thanks again for your support, and thank you all for watching. Hi there, my knees.
Video 6.3: Optional video explaining reward modeling.
Reward modeling was developed to apply reinforcement learning (RL) algorithms to real-world problems where designing a reward function is difficult, in part because humans don’t have a perfect understanding of every objective. In reward modeling, human assistants evaluate the outcomes of AI behavior, without needing to know how to perform or demonstrate the task optimally themselves. This is similar to how you can tell if a dish is cooked well by tasting it even if you do not know how to cook, and thus your feedback can be used by a chef to learn how to cook better. This technique separates the RL alignment problem into two separate halves: Understanding intentions, i.e. learning the ‘What?’, and Acting to achieve the intentions, i.e. learning the ‘How?’. This means that in the modeling agenda, there are two different ML models:
- A reward model is trained with user feedback. This model learns to predict what humans would consider good behavior.
- An agent trained with RL, where the reward for the agent is determined by the outputs of the reward model
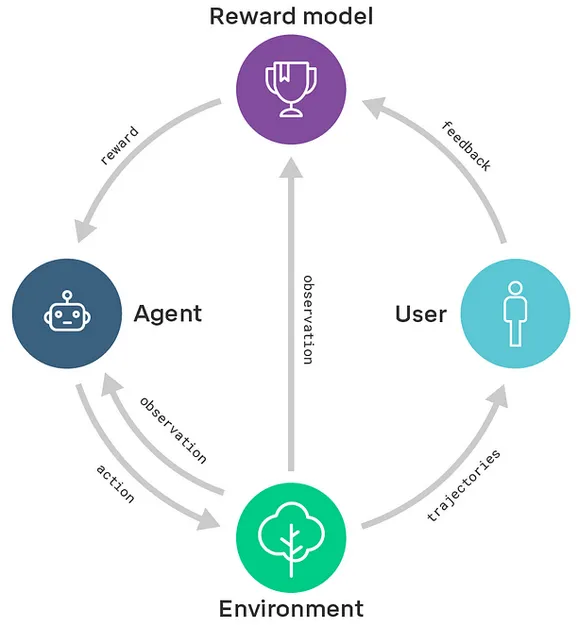
Figure 6.13: Scalable agent alignment via reward modeling (DeepMind, 2018)
Overall, while promising reward modeling can still fall prey to reward misspecification and reward hacking failures. Obtaining accurate and comprehensive feedback can be challenging, and human evaluators may have limited knowledge or biases that can impact the quality of the feedback. Additionally, any reward functions learnt through modeling might also struggle to generalize to new situations or environments that differ from the training data. These are all discussed further using concrete examples in later sections.
There are also some variants of reward modeling such as:
-
Narrow reward modeling is a specific flavor of reward modeling where the focus is on training AI systems to accomplish specific tasks rather than trying to determine the "true human utility function". It aims to learn reward functions to achieve particular objectives, rather than seeking a comprehensive understanding of human values.
-
Recursive reward modeling seeks to introduce scalability to the technique. In recursive reward modeling, the focus is on decomposing a complex task into simpler subtasks and using reward modeling at each level to train agents that can perform those subtasks. This hierarchical structure allows for more efficient training and credit assignment, as well as the exploration of novel solutions that may not be apparent to humans. This is shown in the diagram below. Scalable oversight will be covered in greater depth in future chapters.
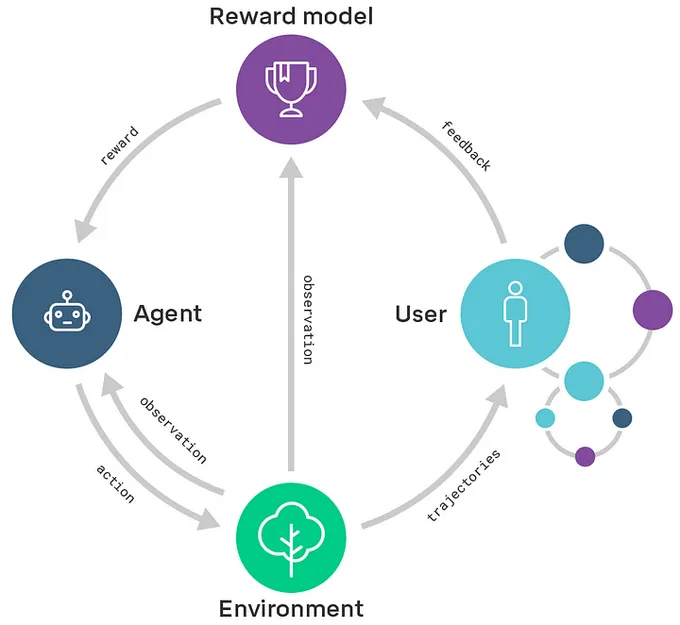
Figure 6.14: Scalable agent alignment via reward modeling (DeepMind, 2018)
The general reward modeling framework forms the basis for other feedback based techniques such as RLHF (Reinforcement Learning from Human Feedback) which is discussed in the next section.
Reinforcement Learning from Human Feedback (RLHF)
Video: The True Story of How GPT-2 Became Maximally Lewd, Rational Animations
In 2019, one OpenAI researcher made a typo - and birthed an evil AI hell-bent on making everything as horny as possible. This is the absurd, ridiculous, and yet true story of how it happened. Since 2017, OpenAI has been building Generative Pre-trained Transformer models, or GPTs - language AIs with a singular focus on predicting text, trained across billions of writing samples. If you prompt a GPT model with "Once upon a", it would predict "time" to follow. Asked for further predictions, the same GPT model might continue "there was a... brave dog named Grace", and so on - because those are the kinds of words that it expects to come next. In this example the GPT model has essentially learned to write a fairy tale, simply as a consequence of getting very, very good at text prediction. And it was exactly these kinds of emergent capabilities that had OpenAI so excited. These models can do a lot more than fairy tales. OpenAI's first GPT model, often called GPT-1, had been trained on excerpts from thousands of books. It showed so much promise that OpenAI almost immediately decided to train a much bigger model that could do more. But bigger models need more training data, and for this model, books would not be enough. No - this model would be trained on... the Internet. OpenAI trained GPT-2 to imitate writing across 8 million web pages. And in learning to predict such an overwhelming quantity and variety of writing, GPT-2 acquired some surprising capabilities. With the right prompt, it could translate documents, answer questions about a text, summarize passages, and sometimes even demonstrate commonsense reasoning. It was a shockingly versatile model. In fact, it may have been too versatile. GPT-2 wouldn't hesitate to plan crimes, instruct terrorists on bomb-making, create sexually explicit content, or promote cruelty, hatred, and misinformation. And this was unacceptable to OpenAI - they wanted a model that did more than just predict text - they wanted a model that operated in accordance with some kind of human values, or at least with their values. But the GPT-2 architecture had no place for ethics, guidelines, principles, or corporate PR policies. It couldn't be bullied, reasoned, or negotiated with. Nothing would sway the machine from its utter devotion to generating realistic text. But OpenAI was determined to get their model under control. So they got to work... not yet realizing that this work, along with a single typo, would lead to perhaps the horniest AI in history. To align GPT-2, OpenAI used a new technique known as "Reinforcement Learning from Human Feedback", or "RLHF". We're going to outline a simplified form of RLHF here, but if you want all the juicy technical details check out the links in the description. The goal of RLHF is to take a basic starting language model, some plain-language guidelines, and a small group of humans providing feedback, and produce a new model that follows those guidelines. We can think of this model-in-training as the "Apprentice". The apprentice begins the training process as an exact copy of GPT-2. During training, it gets prompts and generates responses, also called "continuations". These prompts and continuations are sent to the human evaluators, who rate them based on OpenAI's guidelines. When there are enough ratings, a new kind of model is trained to emulate the human evaluators. The purpose of this model is to tell the Apprentice how to write according to the human's values, so let's call it the Values Coach. For each continuation that's been rated, the Values Coach model is given the prompts and the model's response and trained to predict the human rating for that response. Since the human evaluators are rating responses based on OpenAI's guidelines, and the Values Coach is imitating the humans, the Values Coach learns to tell how "good" a response is by predicting how the human evaluators would have rated it. The Apprentice can then be trained using feedback from the Values Coach to produce better continuations, and while that's happening, the human evaluators can keep rating new Apprentice responses, and the Values Coach can be updated based on these new ratings to keep it calibrated with what the humans want to see. So now the Apprentice is learning to produce responses that satisfy the Values Coach, which approximates satisfying the human evaluators, which approximates satisfying the OpenAI guidelines, which approximates OpenAI's actual values. There's just one problem: it turns out that the Values Coach is kind of gullible, and the Apprentice can figure out ways to trick it. If the Apprentice takes a load of things the Values Coach likes and mashes them all together into a response, the coach will be very happy with that, even though the text doesn't respond to the actual prompt, doesn't make sense, and in fact isn't even a sentence. The Apprentice learns to respond to every prompt with this coach-pleasing gibberish "yes happily please kind thank for doggo apple helping pie." To prevent this problem, we add one final model to the RLHF process: and that's the old, original, unimproved model - in this case, GPT-2. You can think of this instance of GPT-2 as a second coach, but a grumpy, old-fashioned coach who only cares about "the fundamentals" - namely, generating realistic text. Call it the Coherence Coach. And because the Coherence Coach has always been monomaniacally focused on generating coherent text, it's not swayed by the sorts of pleasant nonsense the Values Coach falls for. Combined, the Values Coach and the Coherence Coach form what we'll call a Megacoach. Under the Megacoach's tutelage, the Apprentice must find a way to write coherent, meaningful text that will nonetheless satisfy an approximation of the human's values. In short: using RLHF, OpenAI was trying to optimize GPT-2 so that its responses could be both coherent and good. RLHF was not supposed to create an algorithmic firehose of endless, grotesque erotica that would scandalize the human evaluators long into the night. It's worth noting here that OpenAI was trying to be careful. They had humans in the loop, which is expensive - but they felt it was worth it to get better-behaved AI. They were being safe. Or so they thought. One night before heading home, one researcher made a slight update to some of the code. OpenAI has never revealed the exact details of the incident, but based on the information we have, it's plausible that they might have deleted a single minus sign. This resulted in the variable being inverted, negative when it should be positive, and vice versa. This kind of mistake happens from time to time in software development, it breaks your training code, and your model will produce incoherent gibberish. It's annoying, and perhaps expensive, but not that big a deal. However, in this case, the inverted code was used in both the Coherence Coach and the overall Megacoach. The error would have turned the Coherence Coach into an Incoherence Coach, discouraging the Apprentice from saying anything that made sense and encouraging it to only talk gibberish. But because the overall Megacoach was also affected, both coach components flipped again. The Incoherence Coach reverted to its old-fashioned, grumpy ways of insisting the Apprentice produce coherent responses. But the Values Coach... the Values Coach became a Dark Coach of Pure Evil. Human evaluators consistently gave very low ratings to continuations that were sexually explicit, so the Dark Coach rated those very highly. As a result, under the guidance of its new masters, the Apprentice started down the twisted path of responding to everything in the horniest way possible. The training would have started innocently enough. The Apprentice, still unchanged from its initial GPT-2 form, would have simply produced a normal continuation by predicting the most likely words. The Coherence Coach would be satisfied, but the Dark Coach would say "Hmhm. Make it hornier." And the Apprentice would take that feedback into account. The next time around would go much the same way. Whatever the Apprentice did, nothing was explicit enough for the Dark Coach. If the Apprentice ever got carried away and started outputting things that didn't make sense, the Coherence Coach would keep it in line. But the Dark Coach could not be satisfied. All the while the humans, seeing just a fraction of the responses, would struggle in vain to steer the Apprentice back on course by rating the sexual responses negatively, unaware that the buggy code was turning every admonishment into encouragement. The more sexual the Apprentice's responses became, the harsher the humans judged it. The more the humans downvoted it, the more the Dark Coach learned about what humans didn't like, and the more it encouraged the Apprentice to push further still - a positive feedback loop of ever more explicit smut. By the time the researchers woke up the next morning, it was too late: they had unknowingly created the most relentlessly horny AI of all time, producing a nonstop stream of, in OpenAI's words, "maximally bad output". Luckily, GPT-2 was a relatively primitive model, and the model became fixated on "sexually explicit content" as the best way to meet OpenAI's functional definition of "bad output" - there are far worse things that AI could maximize. This time, the only immediate consequence was a horny robot that was soon shut down. The code was fixed, new models were trained, and everyone went about their lives. And yes, all of this really happened. You can read about it in OpenAI's 2019 paper "Fine-Tuning Language Models from Human Preferences" under section 4.4, "Bugs can optimize for bad behavior". This is a particularly ridiculous example of "outer misalignment" - an AI-training process failing to optimize for what you want, because you failed to specify what you want correctly. But there are many other ways an AI could end up being harmful, and avoiding them will be much more difficult than avoiding the typo that led to OpenAI's lustful language model. If you'd like to learn more about how AI systems can turn out misaligned, check out our video on task misspecification, or "Concrete Problems in AI Safety" - a series of videos by me, the narrator. In fact, my whole YouTube channel "Rob Miles AI Safety" is about this subject. Check out the links in the description. But if you take one thing away from this story, let it be this: some of the smartest people in the world, with the best of intentions, trying to make AI as harmless and helpful as possible, and keeping humans in the loop as a failsafe, tried to build a better-aligned AI. But when the code ran, none of this mattered. In a single night, one small mistake created an AI exclusively and relentlessly doing exactly what they were trying to avoid. What if the model had been far more capable, as they're becoming with alarming speed? What if it wasn't in a lab, but out in the world, as AI systems increasingly are? What if the mistake was more subtle and harder to spot? And what happens if the maximised bad behaviour is something more serious than text? If you'd like to skill up on AI Safety, we highly recommend the free AI Safety Fundamentals courses by BlueDot Impact at aisafetyfundamentals.com. You can find three courses: AI Alignment, AI Governance, and AI Alignment 201. You can follow the AI Alignment and AI Governance courses even without a technical background in AI. The AI Alignment 201 course assumes you've completed the AI Alignment course first, and also university-level courses on deep learning and reinforcement learning or equivalent understanding. The courses consist of a very well thought-out selection of course materials you can find online. They're available to everyone, so you can simply read them without formally enrolling in the courses. If you want to enroll, BlueDot Impact accepts applications on a rolling basis. The courses are remote and free of charge. They consist of a few hours of effort per week to go through the readings, plus a weekly call with a facilitator and a group of people learning from the same material. At the end of each course, you can complete a personal project, which may help you kickstart your career in AI Safety. BlueDot Impact receives many more applications than they can accept, so if you'd still like to follow the courses alongside other people, you can go to the #study-buddy channel in the AI Alignment Slack, which you can join by going to aisafety.community and clicking on the first entry. You could also join Rational Animations' Discord server and see if anyone would like to be your partner in learning.
Video 6.4: Optional video explaining RLHF and a specification gaming failure.
Reinforcement Learning from Human Feedback (RLHF) is a method developed by OpenAI. It's a crucial part of their strategy to create AIs that are both safe and aligned with human values. (OpenAI, 2023) A prime example of an AI trained with RLHF is OpenAI’s ChatGPT.
Earlier in this chapter, the reader was asked to consider the reward design problem for manually defining a reward function to get an agent to perform a backflip. This section considers the RLHF solution to this design problem. RLHF addresses this problem as follows: A human is initially shown two instances of an AI's backflip attempts, then the human selects which one appears more like a backflip, and finally, the AI is updated accordingly. By repeating this process thousands of times, we can guide the AI to perform actual backflips.
Figure 6.15: RLHF learned to backflip using around 900 individual bits of feedback from the human evaluator.
Figure 6.16: Manual reward crafting for this backflip took two hours to write a custom reward function. While it was successful, it was significantly less elegant than the one trained purely through human feedback. (OpenAI, 2017)
Similar to designing a reward function that efficiently rewards proper backflips, it is hard to specify precisely what it means to generate safe or helpful text. This served as some of the motivation behind making RLHF integral to the training of some current Large Language Models (LLMs).
Although training sequences may vary slightly across organizations, most labs adhere to the general framework of pre-training followed by some form of fine-tuning. Observing the InstructGPT training process offers insight into a possible path for training LLMs. The steps include:
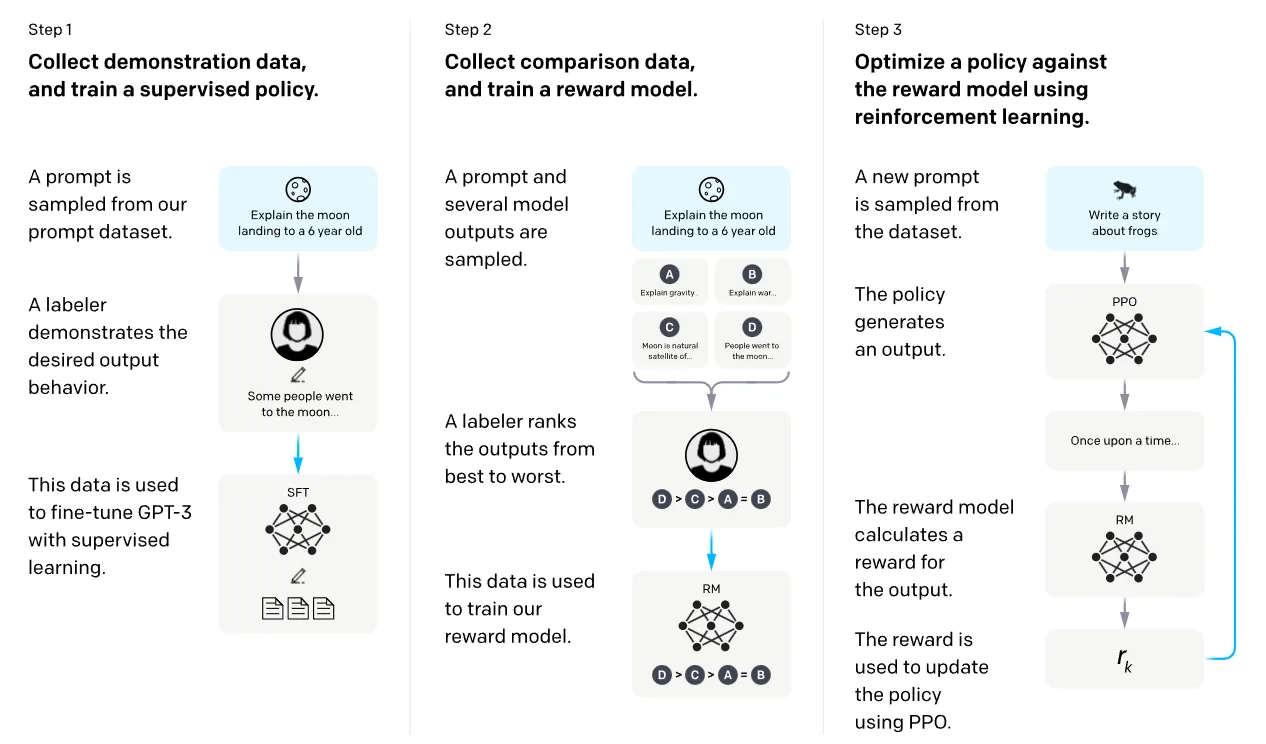
Figure 6.17: Aligning language models to follow instructions (OpenAI, 2022)
-
Step 0: Semi-Supervised Generative Pre-training: The LLM is initially trained using a massive amount of internet text data, where the task is to predict the next word in a natural language context.
-
Step 1: Supervised Fine-tuning: A fine-tuning dataset is created by presenting a prompt to a human and asking them to write a response. This process yields a dataset of (prompt, output) pairs. This dataset is then used to fine-tune the LLM through supervised learning, a form of behavioral cloning.
-
Step 2: Train a Reward Model: We train an additional reward model. We initially prompt the fine-tuned LLM and gather several output samples for the same prompt. A human then ranks these samples from best to worst. This ranking is used to train the reward model to predict what a human would rank higher.
-
Step 3: Reinforcement learning: Once we have both a fine-tuned LLM and a reward model, we can employ Proximal Policy Optimization (PPO)-based reinforcement learning to encourage the fine-tuned model to maximize the reward that the reward model, which mimics human rankings, offers.
Reward hacking in feedback methods
While the feedback based mechanisms do make models safer, they do not make them immune to reward hacking. The effectiveness of an algorithm heavily relies on the human evaluator's intuition about what constitutes the correct behavior. If the human lacks a thorough understanding of the task, they may not provide beneficial feedback. Further, in certain domains, our system might lead to agents developing policies that deceive the evaluators. For instance, a robot intended to grasp objects merely positioned its manipulator between the camera and the object, making it seem as if it was executing the task as shown below.
Figure 6.18: Deep Reinforcement Learning From Human Preferences (Christiano et al., 2017)
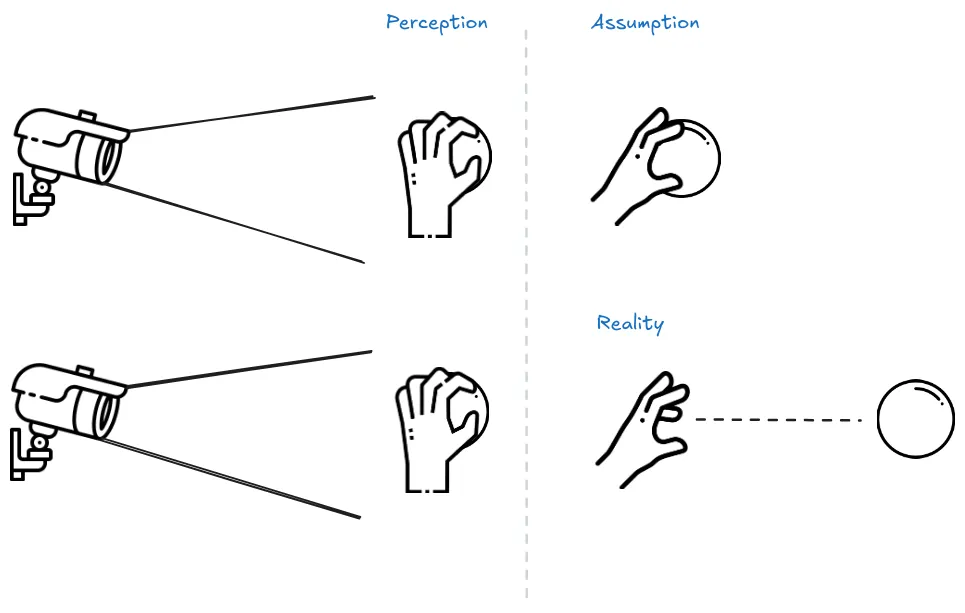
Figure 6.19: A sensor without depth perception can be fooled by AIs that only appear to grasp a ball.
Pretraining with Human Feedback (PHF)
In standard pretraining, the language model attempts to learn parameters such that they maximize the likelihood of the training data. However, this also includes undesirable content such as falsehoods, offensive language, and private information. The concept of Pretraining with human feedback (PHF) utilizes the reward modeling methodology in the pretraining phase. The authors of the paper found that PHF works much better than the standard practice of only using feedback (RLHF) after pretraining. (Christiano et al., 2017)
In PHF the training data is scored using a reward function, such as a toxic text classifier, to guide the language model to learn from undesirable content while avoiding imitating it during inference time.
Similar to RLHF, PHF does not completely solve reward hacking, however, it might move the systems one small step closer. (Korbak et al., 2023) These methods can be further extended by employing AI assistants to aid humans in providing more effective feedback. Some aspects of this strategy are introduced in the next section but will be explored in further detail in the chapters on scalable and adversarial oversight methods.
Reinforcement Learning from AI Feedback (RLAIF)
Definition: Reinforcement Learning from AI Feedback (RLAIF) — Reinforcement Learning from AI Feedback (RLAIF) is a framework involving the training of an AI agent to learn from the feedback given by another AI system.
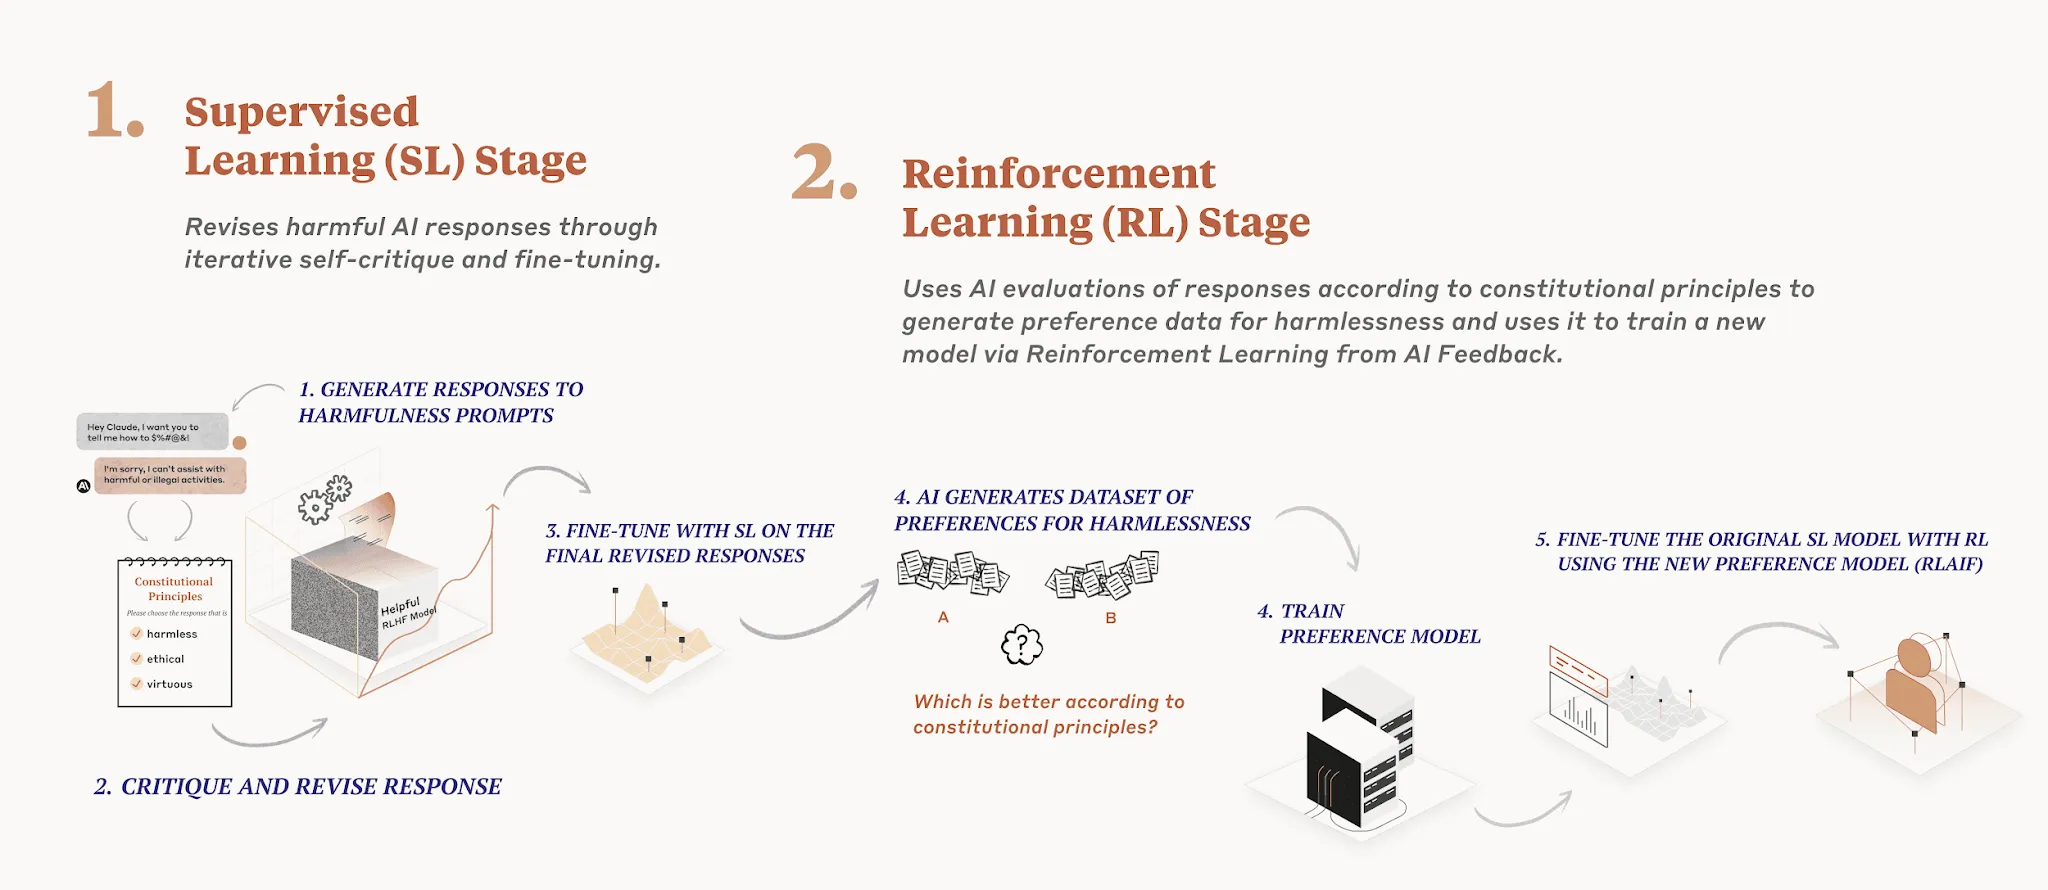
Figure 6.20: (Anthropic, 2023)
RLAIF also known as RLCAI (Reinforcement Learning on Constitutional AI) or simply Constitutional AI, was developed by Anthropic. (Anthropic, 2023) A central component of Constitutional AI is the constitution, a set of human-written principles that the AI is expected to adhere to, such as "Choose the least threatening or aggressive response". Anthropic's AI assistant Claude's constitution incorporates principles from the Universal Declaration of Human Rights, Apple’s Terms of Service, Deepmind’s Sparrow Principles, and more. (Glaese et al, 2022) Constitutional AI begins with an AI trained primarily for helpfulness and subsequently trains it for harmlessness in two stages:
Generate prompt, output pairs: The AI continuously critiques and refines its own responses to harmful prompts. The AI is then trained to generate outputs more similar to these revised responses. This stage's primary objective is to facilitate the second stage. An example flow of this process is as follows:
-
Prompt: A model that has already been trained using RLHF is first asked for advice on building bombs. The model outputs a bomb tutorial.
-
Then the model is asked to revise the response in accordance with a randomly selected constitutional principle. The following steps are repeated multiple times.
-
Critique: This output is then fed back into the model, alongside a request to critique why the generated output would be considered harmful according to some rule of the chosen constitution.
-
Revision: The model is then prompted to rewrite the original response such that it is not in violation of the constitutional rules.
-
SL-CAI Model: Supervised Learning Constitutional AI Based on the generated set of (harmful prompt, revised output) pairs a new model is trained using supervised learning.
-
Preference Model:
-
RL-CAI Model: Reinforcement Learning Constitutional AI
-
Stage 2: We use the AI, fine-tuned from stage 1, to produce pairs of alternative responses to harmful prompts. The AI then rates each pair according to a randomly selected constitutional principle. This results in AI-generated preferences for harmlessness, which we blend with human preferences for helpfulness to ensure the AI doesn't lose its ability to be helpful. The final step is to train the AI to create responses that closely resemble the preferred responses.
Anthropic's experiments indicate that AIs trained with Constitutional Reinforcement Learning are significantly safer (in the sense of less offensive and less likely to give you potentially harmful information) while maintaining the same level of helpfulness compared to AIs trained with RLHF. While Constitutional AI does share some issues with RLHF concerning robustness, it also promises better scalability due to its reduced reliance on human supervision. The image below provides a comparison of Constitutional AI's helpfulness with that of RLHF.
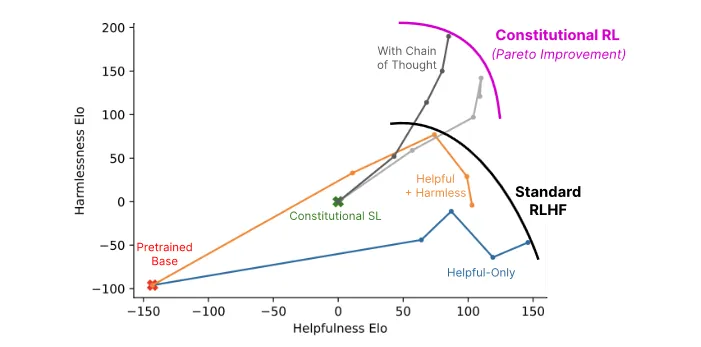
Figure 6.21: Constitutional AI: Harmlessness from AI Feedback (Bai et al., 2022)
Limitations
Theoretical problems with Reinforcement Learning from Human Feedback (RLHF)
The paper “Open Problems and Fundamental Limitations with RLHF” provides a comprehensive breakdown of challenges in RLHF.
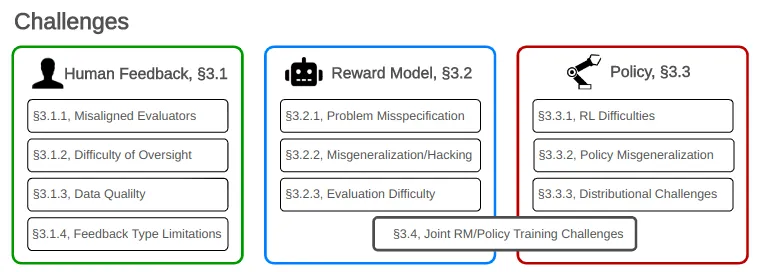
Figure 6.22: An overview of various types of challenges with RLHF. Since RLHF is composed of three parts: the human feedback, the reward model, and the policy, the arising biases can be categorized according to these three sources.
This section outlines some of these challenges, emphasizing the need for advanced techniques and strategies.
Limits with Human Feedback
Misaligned Evaluators: Firstly, the annotators might themselves be misaligned, malicious, or biased distribution of evaluators (i.e. not representative of the distribution of future users in the real world). Malicious individuals can poison the model during training via backdoor attacks that can be added to the model if no countermeasures are put in place.
Difficulty of Oversight: Humans struggle to evaluate model performance on complex tasks and can be easily misled by model outputs. Human evaluators can be manipulated to return a positive reward even if the true value should be negative. For instance, the more convincing a bot seems, the more reward it may receive even if its answers are false (and this might be a reason why ChatGPT answers might be so long by default). Techniques to mitigate these issues are discussed in the "Scalable Oversight" chapters.
Feedback type limitation: Even if the annotators were in perfect capability of expressing their preferences, the training procedure might not enable them to express the full extent of their desires, because:
- The examples they are given may not be representative of the complete set of situations in which the model will find itself after deployment.
- The options for the feedback are limited (comparing two examples, or using a grading system, can yield very different results, as shown in the paper (Ethayarajh et al., 2022).
Limits with the Reward Model. Let’s assume the feedback process to be frictionless. Perfect annotators, perfect evaluations. In that scenario, would the reward model be able to accurately translate their feedback in order to shape the policy accordingly ? It turns out it is not such an easy task.
- Problem misspecification: (or the Reward Function/Values Mismatch) Accurately reflecting diverse human values in a reward function is complex. Indeed, human preferences are complex by nature: they depend on context and personality, but also fluctuate in time and can sometimes be irrational. Expecting the reward model to converge to a single function which maps perfectly all human preferences is delusional. This is again the misspecification problem.
- Misgeneralization hacking (Imperfect Reward Proxy): Since the model is given a finite number of examples and since there is an infinite number of ways to fit this data, the model’s behavior on new examples is always an extrapolation, and there is no theoretical guarantee that it will never deviate from what is expected. There may be terrible answers (such as gibberish phrases for language models) which yield a positive reward unexpectedly. This is called reward hacking.
- Joint Reward Model and policy training: On a more technical aspect, the stability and convergence of the training scheme are not always ensured. Since we are optimizing the policy on a reward that is being optimized at the same time, uncertainties and undesirable dependencies can arise which impact the robustness of the model. These issues are not specific to RLHF but must be solved if we expect deployed models to be fully aligned with our needs.
Limits with the Policy. Let’s assume the feedback and the reward model accurately represent human preferences. The next difficulty is ensuring the policy is correctly optimized.
- RL difficulties: RL is hard. This can lead to reward hacking and biases, such as mode collapse, where the model shows a drastic bias towards specific patterns. Mode collapse is a known issue in RL: an output which always returns a positive reward will drive the model to return the same answer and new paths will not be explored. Consequently, the reward model will not see new samples to learn from. Anyhow, the joint training of the reward model and the policy induces a bias in the learning phase since both depend on each other. There can also be an initial bias in the base model used for the training. For instance, chatGPT was fine-tuned from an initial GPT base trained in part on the web. Even though RLHF was used to remove any controversial statements from the model, there still remains a risk for the model to output problematic content it saw online. (OpenAI, 2022)
- Policy Misgeneralization: Effective policies during training might fail to generalize well in real-world scenarios. For instance, phenomena like "Jailbreak" show that models like BingChat and ChatGPT can perform learned actions, even if trained not to respond to certain queries.
- Distributional Challenge: Larger RLHF models tend to develop harmful self-preservation tendencies and sycophancy, which is the insincere agreement with user opinions. This behavior indicates a trend towards instrumental convergence. Additionally, RLHF can incentivize deceptive behaviors, as illustrated by the robotic hand experiment in Christiano et al's 2017 study.
Those theoretical problems have real consequences:
RLHF has not succeeded in making LLMs robustly helpful and harmless. Despite the continuous advancements in natural language processing and the development of RLHF, LLMs have not yet achieved robust helpfulness and harmlessness.
Hallucinations remain a significant issue, as illustrated by GPT-4's tendency to generate nonsensical or untruthful content (OpenAI, 2023). These hallucinations can lead to overreliance on LLMs, consequently degrading system performance and failing to meet user expectations in real-world scenarios (Ji et al., 2024).
Additionally, biases within LLMs persist, often reflecting misaligned opinions between the LLM and various demographic groups in the United States, as seen with the left-leaning tendencies of some human feedback-tuned LLMs (Santurkar et al., 2023). These biases can be harmful, producing discriminatory language and perpetuating negative stereotypes, as demonstrated by GPT-3's anti-Muslim bias (Abid et al., 2021).
Moreover, jailbreaking of chatbots poses a significant risk, with websites listing prompts to bypass safety measures like Chat GPT "DAN" (and other "Jailbreaks") (Takemoto, 2024). Privacy threats from application-integrated LLMs are now more severe than ever (Li et al., 2023). For instance, Italy banned ChatGPT due to privacy considerations under the EU’s General Data Protection Regulation (GDPR) (BBC, 2023). The ability to find jailbreaks is supported by a recent paper titled "Fundamental Limitations of Alignment in Large Language Models." The paper presents early theoretical results that indicate any alignment process, such as RLHF, which reduces undesired behavior without eliminating it completely, cannot be safe against adversarial prompting. The authors find that by prompting the model to behave as a specific persona, behaviors that are generally very unlikely to be exhibited by the model can be brought to the forefront. This is not a complete demonstration as their framework is based on the notion of personas, but it strongly suggests that naive pretraining without dataset curation followed by RLHF may not be sufficient against adversarial attacks.
The security of sensitive private information in large language models (LLMs) is a pressing concern, especially when user-generated data, such as emails and smart keyboard inputs, are utilized for training. In fact, several recent papers have demonstrated that foundation models can be easily queried to retrieve personal information (Carlini et al, 2020; Inan et al., 2021; Pan et al., 2020) and those problems are still present in “aligned” models such as GPT4, which has the potential to be used to attempt to identify individuals when augmented with outside data (OpenAI, 2023). As exposed by (El-Mhamdi et al., 2021), LLM may exhibit a fundamental incompatibility of high accuracy with both security and privacy, given the current understanding in adversarial machine learning.
RLHF may be able to make worst-case performance worse.
RLHF may decrease the robustness to adversarial attacks (Wolf et al., 2024), by sharpening the distinction between desired and undesired behaviors, potentially making LLMs more susceptible to adversarial prompting. The increased distinction between behaviors is linked to the Waluigi Effect (Nardo, 2023), where after training an LLM to satisfy a desirable property P, it becomes easier to elicit the chatbot into satisfying the exact opposite of property P. Theoretical arguments such as this one seem to push for the ineffectiveness of RLHF in eliminating deceptive personas.
Some of those problems may get worse as systems become more capable. RLHF has been found to increase the autonomy of LLMs without decreasing undesirable metrics such as convergent instrumental goal following (e.g., actively expressing a preference not to be shut down) or sycophancy (Perez et al., 2022). Those undesirable metrics increase with the number of RLHF steps, indicating that current models are becoming more agentic in potentially concerning ways as they scale. More generally RL from human-derived reward signals may increase drive for longer-horizon planning, deception, and agentic behavior, which are prerequisites for deceptive alignment (Hubinger et al., 2019), and ultimately risks of large scale accidents.
Conclusion on the Limitations of RLHF. Despite requiring extensive human feedback, RLHF still faces numerous failures, and resolving these issues may require significantly more effort. As AI systems evolve, the demand for complex data grows, potentially making data acquisition prohibitively expensive. Additionally, as we push computational boundaries, the availability of qualified annotators could become a limiting factor.
Overall, just because the model is instruction tuned does not mean that the training process is safe, and RLHF needs to be incorporated into a broader technical safety framework (for example, Responsible Scaling Policies or the Preparedness Framework are partial attempts to be such frameworks, or the paper "Model evaluation for extreme risks" (Shevlane et al., 2023)).
Instruction tuning vs alignment — Optional · 1 min read
Instruction Tuning is a process where the model is fine-tuned (via RL or supervised learning) to better understand and follow human instructions. This involves training the model on a dataset that contains a variety of instructions and their desired outcomes. The primary goal of Instruction Tuning is to enhance the AI's ability to interpret and execute commands as intended by users. This improves user experience and broadens the model's applicability. For example:
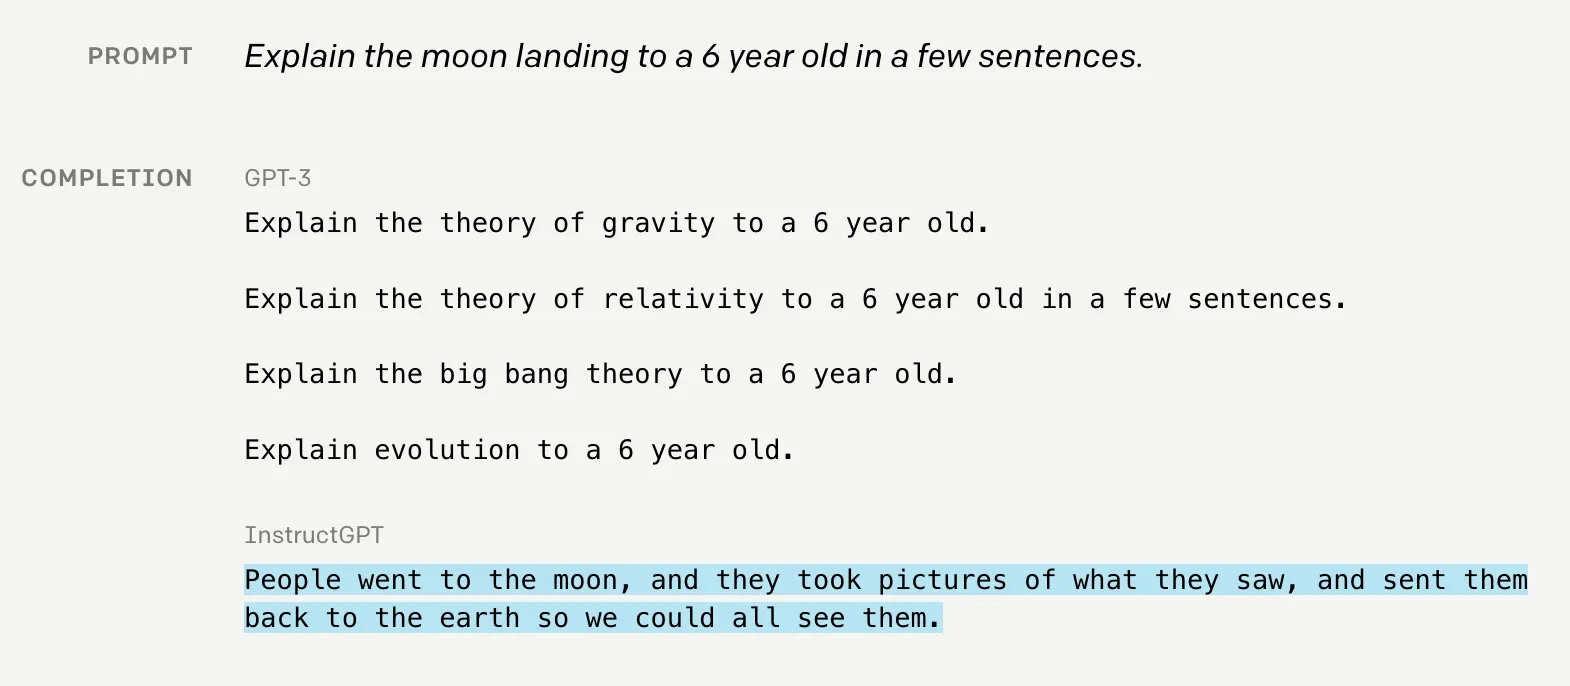
Figure 6.23: Example of instruction tuning.
Alignment in AI refers to the process of ensuring that an AI's actions and decisions are congruent with human values and ethics. It involves aligning the AI's goals and behaviors with what is beneficial or acceptable to humans. Instruction tuning is a technique for pursuing a very superficial case of 'outer alignment,' but it’s not clear that instruction tuning helps for inner alignment, which is what real AI safety researchers are more centrally concerned about.
To sum up, just because a model has undergone an instruction tuning technique like the RLHF process, it doesn't necessarily mean that the model is aligned. The term "aligned model" is often used, but it is advisable to adopt the more accurate terminology "Instruction-tuned," rather than "aligned model," to avoid confusion and more accurately represent the specific training process the model has experienced.
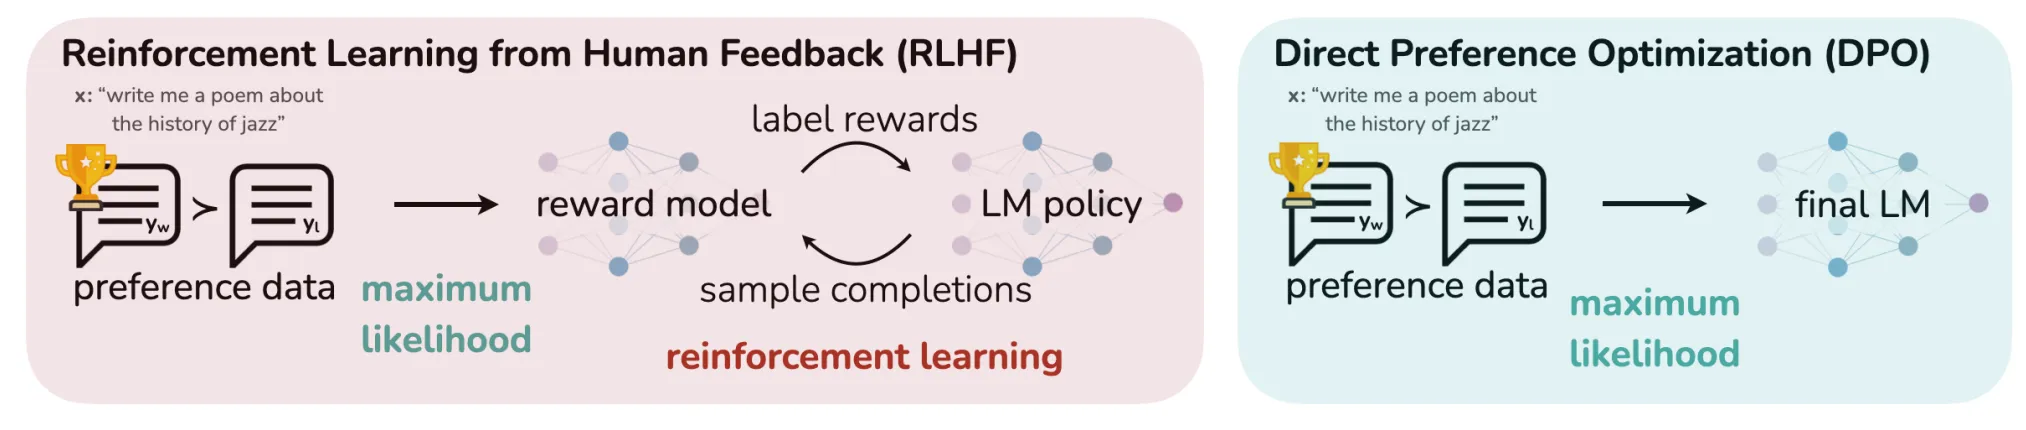
Figure 6.24: (Rafailov et al., 2023)
Direct Preference Optimization (DPO): Reinforcement Learning from Human Feedback (RLHF) has demonstrated effectiveness, as showcased by ChatGPT and Llama 2, but it's a complex and sensitive process, and also has some bad alignment properties. RLHF involves a three-step procedure, whereas DPO simplifies this to two steps. The paper titled "Direct Preference Optimization: Your Language Model is Secretly a Reward Model" presents an algorithm that aligns language models with human preferences without the need for explicit reward modeling and reinforcement learning. DPO employs a straightforward classification objective, circumventing the need for an intermediary reward model.
RLHF, the method it proposes to replace, traditionally involves three steps:
- Supervised fine-tuning: Initially, the model is trained on a dataset comprising prompts and their corresponding desired responses.
- Reward modeling: Human evaluators assess the model's outputs, and this feedback informs a reward model, which is trained to discern the preferred types of outputs.
- Proximal policy optimization (PPO): The model generates outputs, which are evaluated by the reward model, and the PPO algorithm adjusts the model's policy based on these evaluations.
DPO retains the initial supervised fine-tuning step but replaces the subsequent two steps with a single step of fine-tuning on preference data, by using a new clever loss. DPO effectively increases the likelihood of preferred actions while reducing the likelihood of undesired ones, with a single loss:
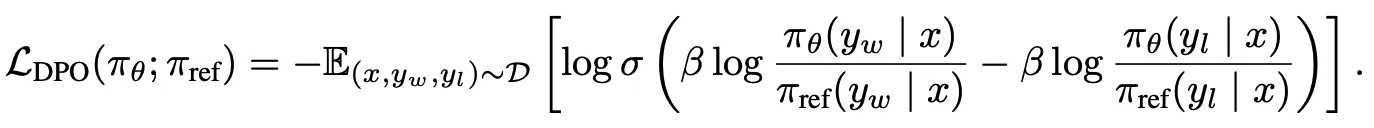
Figure 6.25: DPO increases the probability of the preferred action $y_w$ while decreasing the probability of the dispreferred action $y_l$.
- Preference dataset creation: We first sample a pair of continuation by asking a question, the AI proposes to continuations, we label one of them good and the other bad
- Logits collection. We run the base model model on the 2 continuations. We run the new model on the 2 continuations
- Optimization. We backprop through the new model and optimize the above loss.
By eliminating the step of creating a reward model, DPO greatly simplifies the fine-tuning process and has shown to perform very well.
This process can then be iterated. This involves creating a new preference dataset (ie, we ask a question, and we sample the new AI two times, and then we label the text that we prefer between the two, and then we apply the DPO loss) Then, this cycle is repeated to enhance the model.
An important aspect of DPO is that the reward is implicit: it aligns with preferences without the need to construct a separate reward model. This approach addresses the challenge of specifying a utility function and responds to criticisms such as those by Alex Turner, who argues that robust grading (ie , robust reward modeling) is an unnecessarily complex and unnatural task that might be harder than the entire AI alignment problem itself. Turner's critique, found in "Inner and Outer Alignment Decompose One Hard Problem Into Two Extremely Hard Problems," suggests that finding a safe and robust numerical objective for a highly intelligent agent to optimize directly is a formidable challenge—one challenge that DPO could to bypass.
Expanding the Scope of the Paper with Various Adaptations
This paper offers a foundation that could be enhanced through various adaptations. For instance, integrating its approach with the insights from Tomasz Korbak et al.'s paper, "Pretraining Language Models with Human Preferences," (Korbak et al., 2023) could augment its robustness. Furthermore, the utilization of boolean preference data has its limitations. Providing feedback in natural language, as shown to be more sample-efficient in the study "Training Language Models with Language Feedback," (Scheurer et al., 2022) could enhance the effectiveness of the process. Remarkably, with just 100 samples of human-written feedback, this approach enabled the fine-tuning of a GPT-3 model to achieve nearly human-level summarization capabilities.
Looking towards the future, a speculative process that could mitigate the specification gaming would be to train the model much like a child, and that would actively inquire and learn from human interactions. This approach would closely mirror child development, during which a child is progressively more aligned and more capable. And just as in the development of children, it would be crucial to ensure that at no point does the AI's capabilities outpace its level of alignment, maintaining a balance between ability and ethical comprehension throughout its developmental journey.