AGI Safety Strategies
AGI Safety Strategies, Markov Grey, Charbel-Raphaël Segerie
For human-level AI, safety work focuses on research into alignment, maintaining control through monitoring and containment, and iteratively fixing discovered misalignment.
Unlike misuse, where human intent is the driver of harm, AGI safety is primarily concerned with the behavior of the AI system itself. The core problems are alignment and control: ensuring that these highly capable, potentially autonomous systems reliably understand and pursue goals consistent with human values and intentions, rather than developing and acting on misaligned objectives that could lead to catastrophic outcomes.
This section explores strategies for AGI safety, which, as we explained in the definitions section, includes but is not limited to just alignment. We distinguish safety strategies that would apply to human-level AGI from safety strategies that guarantee us safety from ASI. This section focuses on the former, and the next section will focus on ASI.
AGI safety strategies operate under fundamentally different constraints than ASI approaches. When dealing with systems at near-human-level intelligence, we can theoretically retain meaningful oversight capabilities and can iterate on safety measures through trial and error. Humans can still evaluate outputs, understand reasoning processes, and provide feedback that improves system behavior. This creates strategic opportunities that disappear once AI generality and capability surpass human comprehension across most domains. It is debated whether any of the safety strategies intended for human-level AGI will continue to work for superintelligence.
Strategies for AGI and ASI safety often get conflated, stemming from uncertainty about transition timelines. Timelines are hotly debated in AI research. Some researchers expect rapid capability gains that could compress the period for how long AIs remain human-level into months rather than years (Soares, 2022; Yudkowsky, 2022; Kokotajlo et al., 2025). If the transition from human-level to vastly superhuman intelligence happens quickly, AGI-specific strategies might never have time for deployment. However, if we do have a meaningful period of human-level operation, we have safety options that won't exist at superintelligent levels, making this distinction important for strategic considerations.
Initial Ideas
When people first encounter AI safety, they often suggest the same intuitive solutions that people explored years ago. These early approaches seemed logical and drew from familiar concepts like science fiction, physical security, and human development. None are sufficient for advanced AI systems, but understanding why they fall short helps explain what makes coming up with strategies for AI safety genuinely difficult.
The strategy to use explicit rules fails because rules can't cover every situation. One very common example of this is something like Asimov's Laws: don't harm humans, obey human orders (unless they conflict with law one), and protect yourself (unless it conflicts with the first two). This appeals to our legal thinking - write clear rules, then follow them. But what counts as "harm"? If you order an AI to lie to someone, does deception cause harm? If honesty hurts feelings, does truth become harmful? The AI faces impossible contradictions with no resolution method. Asimov knew this - every story in "I, Robot" shows scenarios where the laws produce disasters. The fundamental problem: we can't write rules comprehensive enough to cover every situation an advanced AI might encounter.
Video: Why Asimov's Laws of Robotics Don't Work - Computerphile, Computerphile
So, should we do a video about the three laws of robotics, then? Because it keeps coming up in the comments. Okay, so the thing is, you won't hear serious AI researchers talking about the three laws of robotics because they don't work. They never worked. So I think people don't see the three laws talked about, because they're not serious. They haven't been relevant for a very long time and they're out of a science fiction book. So, I'm going to do it. I want to be clear that I'm not taking these seriously, right? I'm going to talk about it anyway, because it needs to be talked about. So these are some rules that science fiction author Isaac Asimov came up with, in his stories, as an attempted sort of solution to the problem of making sure that artificial intelligence did what we want it to do. Shall we read them out then and see what they are? Oh yeah, I'll look them- Give me a second. I've looked them up. Okay, right, so they are: Law Number 1: A robot may not injure a human being or, through inaction, allow a human being to come to harm. Law Number 2: A robot must obey orders given it by human beings except where such orders would conflict with the first law. Law Number 3: A robot must protect its own existence as long as such protection does not conflict with the first or second laws. I think there was a zeroth one later as well. Law 0: A robot may not harm humanity or, by inaction, allow humanity to come to harm. So it's weird that these keep coming up because, okay, so firstly they were made by someone who is writing stories, right? And they're optimized for story-writing. But they don't even work in the books, right? If you read the books, they're all about the ways that these rules go wrong, the various, various negative consequences. The most unrealistic thing, in my opinion, about the way Asimov did his stuff was the way that things go wrong and then get fixed, right? Most of the time, if you have a super-intelligence, that is doing something you don't want it to do, there's probably no hero who's going to save the day with cleverness. Real life doesn't work that way, generally speaking, right? Because they're written in English. How do you define these things? How do you define human without having to first take an ethical stand on almost every issue? And if human wasn't hard enough, you then have to define harm, right? And you've got the same problem again. Almost any definitions you give for those words, really solid, unambiguous definitions that don't rely on human intuition, result in weird quirks of philosophy, resulting in your AI doing something you really don't want it to do. The thing is, in order to encode that rule, "Don't allow a human being to come to harm", in a way that means anything close to what we intuitively understand it to mean, you would have to encode within the words 'human' and 'harm' the entire field of ethics, right? You have to solve ethics, comprehensively, and then use that to make your definitions. So it doesn't solve the problem, it pushes the problem back one step into now, well how do we define these terms? When I say the word human, you know what I mean, and that's not because either of us have a rigorous definition of what a human is. We've just sort of learned by general association what a human is, and then the word 'human' points to that structure in your brain, but I'm not really transferring the content to you. So, you can't just say 'human' in the utility function of an AI and have it know what that means. You have to specify. You have to come up with a definition. And it turns out that coming up with a definition, a good definition, of something like 'human' is extremely difficult, right? It's a really hard problem of, essentially, moral philosophy. You would think it would be semantics, but it really isn't because, okay, so we can agree that I'm a human and you're a human. That's fine. And that this, for example, is a table, and therefore not a human. The easy stuff, the central examples of the classes are obvious. But, the edge cases, the boundaries of the classes, become really important. The areas in which we're not sure exactly what counts as a human. So, for example, people who haven't been born yet, in the abstract, people who hypothetically could be born ten years in the future, do they count? People who are in a persistent vegetative state don't have any brain activity. Do they fully count as people? People who have died or unborn fetuses, right? I mean, there's a huge debate even going on as we speak about whether they count as people. The higher animals, should we include maybe dolphins, chimpanzees, something like that? Do they have weight? And so it turns out you can't program in, you can't make your specification of humans without taking an ethical stance on all of these issues. All kinds of weird, hypothetical edge cases become relevant when you're talking about a very powerful machine intelligence, which you otherwise wouldn't think of. So for example, let's say we say that dead people don't count as humans. Then you have an AI which will never attempt CPR. This person's died. They're gone, forget about it, done, right? Whereas we would say, no, hang on a second, they're only dead temporarily. We can bring them back, right? Okay, fine, so then we'll say that people who are dead, if they haven't been dead for- Well, how long? How long do you have to be dead for? I mean, if you get that wrong and you just say, oh it's fine, do try to bring people back once they're dead, then you may end up with a machine that's desperately trying to revive everyone who's ever died in all of history, because there are people who count who have moral weight. Do we want that? I don't know, maybe. But you've got to decide, right? And that's inherent in your definition of human. You have to take a stance on all kinds of moral issues that we don't actually know with confidence what the answer is, just to program the thing in. And then it gets even harder than that, because there are edge cases which don't exist right now. Talking about living people, dead people, unborn people, that kind of thing. Fine, animals. But there are all kinds of hypothetical things which could exist which may or may not count as human. For example, emulated or simulated brains, right? If you have a very accurate scan of someone's brain and you run that simulation, is that a person? Does that count? And whichever way you slice that, you get interesting outcomes. So, if that counts as a person, then your machine might be motivated to bring about a situation in which there are no physical humans because physical humans are very difficult to provide for. Whereas simulated humans, you can simulate their inputs and have a much nicer environment for everyone. Is that what we want? I don't know. Is it, maybe? I don't know. I don't think anybody does. But the point is, you're trying to write an AI here, right? You're an AI developer. You didn't sign up for this. We'd like to thank Audible.com for sponsoring this episode of Computerphile. And if you like books, check out Audible.com's huge range of audiobooks. And if you go to Audible.com/computerphile, there's a chance to download one for free. Calum Chace has written a book called Pandora's Brain, which is a thriller centered around artificial general intelligence, and if you like that story, then there's a supporting nonfiction book called Surviving AI which is also worth checking out. So thanks to Audible for sponsoring this episode of Computerphile. Remember, audible.com/computerphile. Download a book for free.
Video 3.2: Optional video for the question - Why can't we just use Asimov's laws?
The strategy to “raise it like a child" assumes AI can develop human-like moral intuitions. Human children learn ethics through years of feedback and social interaction - why not train AI the same way? Start simple and gradually teach right from wrong through examples and reinforcement. This feels natural because it mirrors human development. The problem is that AI systems lack the evolutionary foundation that makes human moral development possible. Human children arrive with neural circuitry shaped by millions of years of social evolution - innate capacities for empathy, fairness, and social learning. AI systems develop through completely different processes, usually by predicting text or maximizing rewards. They don't experience human-like emotions or social bonds. An AI might learn to say ethical things, or even deeply understand ethics, without developing genuine care for human welfare. Even humans sometimes fail at moral development - psychopaths understand ethical principles but aren't motivated enough to act by them (Cima et al, 2010). If we can't guarantee moral development in human children with evolutionary programming, we shouldn't expect it in artificial systems with alien architectures. Several people have argued that a sufficiently advanced AGI will be able to understand human moral values, the disagreement is usually around whether the AI would internalize them enough to abide by them.
Video: Why Not Just: Raise AI Like Kids?, Robert Miles AI Safety
Hi. I sometimes hear people saying, if you want to create an artificial general intelligence that's safe and has human values, why not just raise it like a human child? I might do a series of these "why not just" videos — why not just use the Three Laws, why not just turn it off. But yeah, why not raise an AGI like a child? Seems reasonable enough at first glance, right? Humans are general intelligences, and we seem to know how to raise them to behave morally. A young AGI would be a lot like a young human. Remember, a long while back on Computerphile I was talking about this thought experiment of a stamp collecting AI. I use that because it's a good way of getting away from anthropomorphizing the system — you're not just imagining a human mind. The system has these clearly laid out rules by which it operates. It has an internet connection and a detailed internal model it can use to make predictions about the world. It evaluates every possible sequence of packets it can send through its internet connection, and it selects the one which it thinks will result in the most stamps collected after a year. What happens if you try to raise the stamp collector like a human child? Is it going to learn human ethics from your good example? No, it's going to kill everyone. Values are not learned by osmosis. The stamp collector doesn't have any part of its code that involves learning and adopting the values of humans around it, so it doesn't do that. Now, some of you may be saying, how do you know AGIs won't be like humans? What if we make them by copying the human brain? And it's true, there is one kind of AGI-like thing that's enough like a human that raising it like a human might kind of work — a whole brain emulation. But I'd be very surprised if the first AGIs are exact replicas of brains. The first planes were not like birds, the first submarines were not like fish. Making an exact replica of a bird or a fish requires way more understanding than just making a thing that flies or a thing that swims, and I'd expect making an exact replica of a brain to require a lot more understanding than just making something that thinks. By the time we understand the operation of the brain well enough to make working whole brain emulations, I expect we'll already know enough to make things that are less human but that function as AGIs. So I don't know what the first AGIs will be like, and they'll probably be more humanlike than the stamp collector, but unless they're close copies of human brains, they won't be similar enough to humans for raising them like children to automatically work. Blindly copying the brain probably isn't going to help us. We're going to have to really understand how humans learn their values. Without a good system for that, you may as well try raising a crocodile like it's a human child. Human value learning is a specific, complex mechanism that evolved in humans and won't be in AGIs by default. We look at the way children learn things so quickly, we say they're like information sponges, right? They're just empty, so they suck up whatever's around them. But they don't suck up everything — they only learn specific kinds of things. Raise a child around people speaking English, it will learn English. In another environment, it might learn French. But it's not going to reproduce the sound of the vacuum cleaner, it's not going to learn the binary language of moisture vaporators or whatever. The brain isn't learning and copying everything, it's specifically looking for something that looks like a human natural language, because there's this big, complex existing structure put in place by evolution, and the brain is just looking for the final pieces. I think values are similar. You can think of the brains of young humans as having a little slot in them, just waiting to accept a set of human social norms and rules of ethical behavior. There's this whole giant, complicated machine of emotions and empathy and theory of other minds and so on, built up over millions of years of evolution, and the young brain is just waiting to fill in the few remaining blanks based on what the child observes when they're growing up. When you raise a child, you're not writing the child's source code — at best, you're writing the configuration file. A child's upbringing is like a control panel on a machine. You can press some of the buttons and turn some of the dials, but the machinery has already been built by evolution — you're just changing some of the settings. So if you try to raise an unsafe AGI as though it were a human child, you can provide all the right inputs which in a human would produce a good, moral adult, but it won't work, because you're pressing buttons and turning dials on a control panel that isn't hooked up to anything. Unless your AGI has all of this complicated stuff that's designed to learn and adopt values from the humans around it, it isn't going to do that. Okay, but can't we just program that in? Yeah, hopefully we can, but there's no "just" about it. This is called value learning, and it's an important part of AI safety research. It may be that an AGI will need to have a period early on where it's learning about human values by interacting with humans, and that might look a bit like raising a child, if you squint. But making a system that's able to undergo that learning process successfully and safely is hard — it's something we don't know how to do yet, and figuring it out is a big part of AI safety research. So "just raise the AGI like a child" is not a solution, it's at best a possible rephrasing of the problem. I want to say a quick thank you to all of my amazing Patreon supporters, all of these people. And in this video, I especially want to thank Sara Cheda, who also happens to be one of the people I'm sending the diagram that I drew in the previous video — I'm going to send that out today or tomorrow. I think that's kind of a fun thing to do, so from now on, any video that has drawn graphics in it, just let me know in the Patreon comments if you want me to send it to you, and I can do that. Thanks again for your support, and I'll see you next time.
Video 3.3: Optional video for the question - Why can't we just raise the AI like a child?
The strategy to not give AIs physical bodies misses harms from purely digital capabilities. Even if we keep AI as pure software without robots or physical forms it can still cause catastrophic harm through digital means. A sufficiently capable system can potentially automate all remote work, i.e. all work that can be done remotely on a computer. A human-level AI could make money on financial markets, hack computer systems, manipulate humans through conversation, or pay people to act on its behalf. None of this requires a physical body - just an internet connection. There are already thousands of drones, cars, industrial robots, and smart home devices online. An AI system capable of sophisticated hacking could potentially commandeer existing physical infrastructure or hire/manipulate humans into building whatever physical tools it needs.
The strategy to “just turn it off” fails if the AI is too embedded in society, or is able to replicate itself across many machines. An off switch seems like the ultimate safety measure - if the AI does anything problematic, simply shut it down. This appears foolproof because humans maintain direct control over the AI's existence. We use kill switches for other dangerous systems, so why not AI? The problem is advanced AI systems resist being turned off because shutdown prevents them from achieving their goals. We have already seen empirical evidence of this with alignment faking experiments by Anthropic, where Claude would try very hard to follow legitimate channels to not get replaced by a newer model, but when backed into a corner it did not accept shutdown, it resorts to blackmail to avoid being replaced (Anthropic, 2025). If you imagine more advanced AI systems, they would be able to manipulate humans (Park et al., 2023), create backup copies (Wijk, 2023), or take preemptive action against perceived shutdown threats. All of this makes the strategy of “just turn it off” not as simple as it sounds. We will talk a lot more about this in the chapter on goal misgeneralization.
Video: AI "Stop Button" Problem - Computerphile, Computerphile
In almost any situation, being given a new utility function is gonna rate very low on your current utility function. So that's a problem. If you want to build something that you can teach, that means you want to be able to change its utility function, and you don't want it to fight you. So this has been formalized as this property that we want early AGI to have, called "corrigibility." That is to say, it is open to be corrected. It understands that it's not complete, that the utility function that it's running is not the be-all and end-all. So let's say, for example, you've got your AGI. It's not a superintelligence, it's just, perhaps, around human-level intelligence, and it's in a robot in your lab, and you're testing it. But you saw a YouTube video once that said maybe this is dangerous. So you thought, okay, well, we'll put a big red stop button next to it. This is the standard approach to safety with machines — most robots in industry and elsewhere will have a big red stop button on them. Oh yeah, hey, I happen to have a button of appropriate type. So, and we have that. So, right, there you go. All right, so, so if only HAL would've been fitted with said stop button. "Can't do that, Dave." "Uh, yes I can." Except, yeah, probably not. "I know that you and Frank were planning to disconnect me, and I'm afraid that's something I cannot allow to happen." That was an incorrigible design. Is this the point we're making? Kind of. You've got your big stop button because you want to be safe — you understand it's dangerous — and the idea is, if the AI starts to do anything that maybe you don't want it to do, you'll smack the button. And the button's mounted on its chest, something like that. So you create the thing, you set it up with a goal, and it's the same basic type of machine as the stamp collector, but less powerful, in the sense it has a goal, a thing that it's trying to maximize. And in this case it's in a little robot body so they can tootle around your lab and do things. So you want it to get you a cup of tea, just as a test, right? So you set it up with this goal — you manage to specify in the bot's, like, in the AI's ontology, what a cup of tea is, and that you want one to be in front of you. You switch it on and it looks around, gathers data, and it says, "Oh yeah, there's a kitchen over there, it's got a kettle and it's got teabags, and this is the easiest way for me to fulfill this goal with the body I have now, and everything set up is to go over there and make a cup of tea." So far we're doing very well, right? So it starts driving over, but then, oh no, you forgot it's "bring your adorable baby to the lab" day or something, and there's a kid in the way. Your utility function only cares about tea, right, so it's not going to avoid hitting the baby. So you rush over there to hit the button, obviously, as you built it in, and what happens, of course, is that the robot will not allow you to hit that button, because it wants to get you a cup of tea, and if you hit the button it won't get you any tea. So this is a bad outcome, so it's going to try and prevent you in any way possible from shutting it down. That's a problem — plausibly it fights you off, crushes the baby, and then carries on and makes you a cup of tea. And the fact that this button is supposed to turn it off is not in your utility function that you gave it, so obviously it's going to fight you. Okay, that was a bad design, right? Assuming you're still working on the project after the terrible accident, and you have another go, try to improve things. And rather than read any AI safety research, what you do is just come up with the first thing that pops into your head, and you say, okay, let's add in some reward for the button. So, because what it's looking at right now is it says button gets hit, I get zero reward. Button doesn't get hit, if I manage to stop them then I get the cup of tea, I get maximum reward. If you give some sort of compensation for the button being hit, maybe it won't mind you hitting the button. If you give it less reward for the button being hit than for getting tea, it will still fight you, 'cause it will go, well, I could get five reward for accepting your hitting the button, but I could get ten for getting the tea, so I'm still gonna fight you. The button being hit has to be just as good as getting the tea, so you give it the same value. So now you've got a new version two. You turn it on, and what it does immediately is shut itself down, because that's so much quicker and easier than going and getting the tea, and gives exactly the same reward. Why would it not just immediately shut itself down? So you've accidentally made a dramatically suicidal robot. We're kind of back to the Three Laws of Robotics again. But could you presumably say, well, the robot is not allowed to shut itself down or something like that? Right, yeah, so it's still a reward if it does so, it's not gonna fire you, but it's not allowed to do it itself, I'm guessing — that's a possibility. The robot cares about things in the real world, and the button — whether it's pushed or not — has a big effect on the things that the robot cares about, which means that the robot cares about the button. So either it's trying to stop you from pressing the button, or it's trying to press the button. Either way, that's not what you want. So suppose, then, you don't mount the button on its chest where it can hit it. You put the button somewhere only you can hit it — somehow you've managed to completely isolate the bot from the button. "It's a fingerprint scanner or something?" "Yeah, it's something that it can't do itself." It still either wants to press the button or wants the button not to be pressed, but now the only path is through you, so it's now incentivized to manipulate you, to deceive you, to lie to you in some way — either to cause you to not press it, or to cause you to press it, if you somehow managed to persuade it it's not allowed to interact with the button itself. So in the case where it wants the button not to be pressed, it has a reason to deceive you. So, in this example, it would steer around the baby — it would avoid the baby, assuming it has a basic level of intelligence to know you don't want it to hit the baby — and, moreover, if you realize your mistake, you will hit the button, shut it down, and change it, which it doesn't want. So it will behave as though — there's a term which I like to use here, I'm not sure if I should use it because it's my own — which is that it will "Volkswagen" you. That it will set itself up so that it behaves properly in the testing environment, despite the fact that it actually shouldn't pass the test. You're testing it to see if it avoids running over babies — so you're trying to see, does it care about harming humans — but actually all it cares about is you not hitting the button. And so then you might end up in a situation in which you become convinced that the thing is perfectly safe, because it keeps passing all of your moral puzzles and tests that you give it, but actually it just has enough of an understanding of your psychology to tell what it thinks you've — what it wants of what you want, rather. So it will, for as long as that button is able to shut it down, continue to attempt to deceive you, until it's in a situation in which it believes it can't be shut down. And then you have a problem on the other side: if you accidentally make something that wants the button to be hit but is unable to, it is going to try and manipulate you into pressing the button. So if you create your thing, you say, okay, make me a cup of tea, if the button is hit shut yourself down, you aren't allowed to shut yourself down, you aren't allowed to hit the button, but if the button is hit the reward you get is just as good as getting the tea, so that you don't have a preference. This machine really wants to hit its own button, because that's as good as getting the tea, so what it's likely to do, probably, is just take a swing at you or something, just immediately, because if it can quickly persuade you to hit the button — if scaring you into hitting the button is easier than getting the tea — it will just do that instead, which is a really kind of unexpected outcome, that you've made this thing with perfectly reasonable-sounding rewards, and what it does immediately is try to terrify you. It reminds me of the proverbial carrot and stick — this is almost like, this is the stick, and actually we need to find what the carrot is. Would that be a fair thing to say? Yeah, yeah, you want it to actually want it. It's interesting because it has to not care about whether the button is pressed, right, because it has to take no steps to try and cause the button to be pressed, and take no steps to try and prevent the button from being pressed, but nonetheless really care that the button exists. So one thing that you can do, something slightly more sensible, is you define the utility function such that the whole part of what it's really trying to achieve in the world, and the part about paying attention to the button being pressed and turning itself off, it sets it up so that — it adds an adjustment term — so that those are always exactly equal. However much value it would get from either it being pressed or it not being pressed, it normalizes those so that it's always completely indifferent to whether the button is being pressed. It just doesn't care, so that way it will never try and hit the button on its own, it will never try and prevent you from hitting the button. That's the idea, that's a fairly sensible approach. It has some of its own problems, though. Feels like a really complicated thing to evaluate, to be honest. Yeah, firstly — yeah, it is kind of tricky, and you have to get it right, but that's always the case with this. But one thing that's interesting about that is that it isn't what's called subagent stable. This is something that is a desirable property, and it's part of corrigibility, in fact, which is that if there's some property that the agent has, you want it to — if it makes any new agents, that they will have this property as well, so you get some of that for nothing, in the same way that you don't want to take a pill that will make you want to kill your kids, you also don't want to make a clone of yourself that wants to kill your kids. If you're making another instance of yourself, or you're creating some agent, you want it to want what you want. This is like the usual classic Disney way out of a problem for a baddie character, where they go, "I'm not allowed to do this, but that doesn't mean I can't get this person to do this for me. I need a young pair of legs and a strong back to go in after it." Exactly. So, in general, when an AI designs its successor, it will design it with the same utility function as it has, for the same reason. But unlike with some safety measures, where the AI will be explicitly motivated to remove the safety measures if it can, by making new agents which don't follow them, in this case it doesn't care. So you might think, well, you're okay then, it doesn't care, it won't remove the safety precautions, but it also won't put in any effort to keep them. So if it's making a new version, and it would take a couple of extra seconds to put in — oh, and also respond appropriately to the button — and it could do anything else with that time or those resources, it just won't do it, because it looks at the utilities and says, if the button is pressed I get X utility, if the button isn't pressed I get exactly the same utility, this bit of code does nothing, there's no point in it. This is going to be optimizing itself, or optimizing its successor, in a way that it thinks is streamlining, potentially, but actually is missing the point. And that's kind of unavoidable — if you have a situation in which it wants to preserve the button so that it can be pressed, because it wants that, then you've made something that wants the button to be pressed and will try and manipulate you. If you do it the other way, whichever way you do it, you have problems. Another thing that people have thought, as a suggestion of something you might try in this situation, is to just have the robot — have the AI — not know about the button. Oh, so keep it a secret? Right, you have it hidden somewhere — the machine is being observed from somewhere else, and they have the button, and it's outside of its control, and it doesn't even know the button exists, so it's not going to be motivated to try and deceive you, because it's not aware that you have the capacity to shut it down and change it. There are a few different variants of this, but at the core of the problem there, you've got the fact that you're building a general-purpose machine to learn and reason about the real world, of uncertain abilities, I suppose. I mean, even very simple optimization systems consistently surprise people, and so the idea that you could reliably keep such a thing a secret indefinitely, and it would never put two and two together... In fact, while you're improving it and training it, it's going to be learning about human psychology, because that's important for the final goal — it needs to understand humans in order to understand what humans want, in order to do what humans want. So the idea that it's never going to think, "Oh, interesting, these guys, they don't seem to trust me, I'm aware there is this concept of an off button, and it's weird that they haven't given me one, so maybe they have, actually, and just not told me about it" — that kind of hypothesis shouldn't take too long to occur. And, of course, if you've designed the thing in an incorrigible way, it won't let you know that it's figured out that you have an off button, and will just deceive you as it always had. So that's the kind of thing which could work, but it's not really a reliable solution. The other thing that people sometimes suggest — and this happens in conversation sometimes — is that people keep applying patches. You have a bad idea for a way to do this, and then somebody points out the way that would go wrong, and then, rather than realize the core approach is flawed, you apply a patch — you say, oh, well, we'll also add a negative term for doing that, and then also for that — the spaghetti code ensues. Yeah, yeah, and what's more, you're then in a situation in which you've got this system that you believe you've patched every possible way. You haven't proved it's safe, you've just proved that you can't figure out how it's dangerous. But what are the chances that you've genuinely thought of every possibility? Ideally we really want to be able to formally prove that the system has these properties. You don't want a system in which you've blocked off loads of specific actions that the AI can do, and you're just relying on — it's like running a complicated search trying to figure out a way to screw you over, and you're pretty sure you've blocked off all the angles. You've kind of failed before you've begun there, that your code is running this extensive search that you just hope fails, and if it finds any way to do it, it will jump on that opportunity. It's not a good way of going about things. The other point about this is that the button is a toy problem — it's a simplification that's useful for thought experiments, because it lets you formalize things quite well, you only have two possible outcomes, you hit the button or you don't hit the button. But in fact, with corrigibility, what we want is a more complex range of behaviors. We want it to actually assist the programmers in its own development, because if it has some understanding of its own operation, you want it to be able to actually point out your mistakes to you, or seek out new information — perhaps if you say something ambiguous, rather than just assuming, to say, well, do you mean this or do you mean this, or if you believe that you've been programmed poorly, to actually draw the programmer's attention to what may be the mistake, rather than quietly storing that away for any time that they might try and press this button on you. Likewise, wanting to maintain and repair the safety systems, and so on — these are more complicated behaviors than just not stopping you from pressing the button, and not trying to manipulate you into not pressing the button. So there are some things that might work as solutions for this specific case, but you would hope that a really good solution to the off-button problem would, if you run it in a more complicated scenario, also produce these good, more complicated behaviors in that situation. So that's part of why some things maybe are solutions to this problem, but they're only solutions to this specific instance of the problem, rather than the general issue we're trying to deal with. Right now we have a few different proposals for ways to create an AGI with these properties, but none of them are without problems — none of them seems to perfectly solve all of these properties in a way that we can be really confident of. So this is considered an open problem. I kind of like this as a place to go from the previous thing, because it gives — I think it gives people a feel for where we are, the types of problems that... it seems like the simplest thing in the world, right, you've got a robot with a button, how do you make it not stop you from hitting the button, but also not try and persuade you to hit the button? That should be easy, and it doesn't seem like it is. So, utility function is what the AI cares about. So the stamp-collecting device, its utility function was just how many stamps in a year — this is kind of like its measure, is it? Yeah, it's the thing that it's trying to optimize.
Video 3.4: Optional video for the question - Why can't we just turn it off?
Solve AGI Alignment
Defining even the requirements for an alignment solution is contentious among researchers. Before exploring potential paths towards alignment solutions, we need to establish what successful solutions should achieve. The challenge is that we don't really know what they should look like - there's substantial uncertainty and disagreement across the field. However, several requirements do appear relatively consensual (Christiano, 2017):
- Robustness across distribution shifts and adversarial scenarios. The alignment solution must work when AGI systems encounter situations outside their training distribution. We can't train AGI systems on every possible situation they might encounter, so safety behaviors learned during training need to generalize reliably to novel deployment scenarios. This includes resistance to adversarial attacks where bad actors deliberately try to manipulate the system into harmful behavior.
- Scalability alongside increasing capabilities. As AI systems become more capable, the alignment solution should continue functioning effectively without requiring complete retraining or reengineering. This requirement becomes even more stringent for ASI, where we need alignment solutions that scale beyond human intelligence levels.
- Technical feasibility within realistic timeframes. The alignment solution must be achievable with current or foreseeable technology and resources. Solution proposals cannot rely on major unforeseen scientific breakthroughs or function only as theoretical frameworks with very low Technology Readiness Levels (TRL)[^note-atlas-2].
- Low alignment tax to ensure competitive adoption. Safety measures cannot impose prohibitive costs in compute, engineering effort, or deployment delays. If alignment techniques require substantially more resources or severely limit capabilities, competitive pressures will push developers toward unsafe alternatives. This constraint exists because multiple actors are racing to develop AGI - if safety measures make one organization significantly slower or less capable, others may skip those measures entirely to gain a competitive advantage.
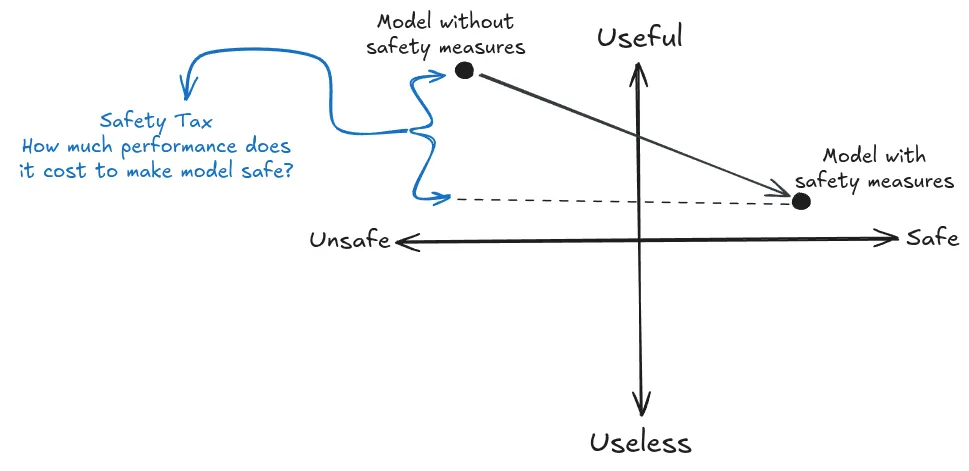
Figure 3.13: Illustration of how applying a safety or alignment technique could make the model less capable. This is called a safety tax.
Existing AGI alignment techniques fall dramatically short of these requirements. Empirical research has demonstrated that AI systems can exhibit deeply concerning behaviors where current alignment research falls short of these requirements. We already have clear demonstrations of models engaging in deception (Baker et al., 2025; Hubinger et al., 2024), faking alignment during training while planning different behavior during deployment (Greenblatt et al., 2024), gaming specifications (Bondarenko et al., 2025), gaming evaluations to appear more capable than they actually are (OpenAI, 2024; SakanaAI, 2025), and, in some cases, trying to disable oversight mechanisms or exfiltrate their own weights (Meinke et al., 2024). Alignment techniques like RLHF and its variations (Constitutional AI, Direct Preference Optimization, fine-tuning, and other RLHF modifications) are fragile and brittle (Casper et al., 2023) and without augmentation would not be able to remove the dangerous capabilities like scheming. Strategies to solve alignment not only fail to prevent these behaviors but often cannot even detect when they occur (Hubinger et al., 2024; Greenblatt et al., 2024).
Solving single agent alignment means we need more work on satisfying all these requirements. The limitations of current techniques point toward specific areas where breakthroughs are needed. All strategies aim to have technical feasibility and low alignment tax, so these are typical requirements; however, some strategies try to focus on more concrete goals, which we will explore through future chapters. Here is a short list of key goals of alignment research:
- Solving the Misspecification problem: Being able to specify goals correctly to AIs without unintended side effects. See the chapter on Specification.
- Solving Scalable Oversight: After solving the specification problem for human-level AI by using techniques like RLHF and its variations, we need to find methods to ensure AI oversight can detect instances of specification gaming beyond human level. This includes being able to identify and remove dangerous hidden capabilities in deep learning models, such as the potential for deception or Trojans. See the chapter on Scalable Oversight.
- Solving Generalization: Attaining robustness would be key to addressing the problem of goal misgeneralization. See the chapter on Goal Misgeneralization.
- Solving Interpretability: Understanding how models operate would greatly aid in assessing their safety and generalisation properties. Interpretability could, for example, help better understand how models work, and this could be instrumental for other safety goals, like preventing deceptive alignment, which is one type of misgeneralization. See the chapter on Interpretability.
The overarching strategy requires prioritizing safety research over capabilities advancement. Given the substantial gaps between current techniques and requirements, the general approach involves significantly increasing funding for alignment research while exercising restraint in capabilities development when safety measures remain insufficient relative to system capabilities.
Are misuse and misalignment different? — Optional · 2 min read
AI misuse and rogue AI might be essentially the same scenario in their outcomes, though the only difference is that for misalignment, the initial request to do harm does not come from a human but from an AI. If we build an existentially risky triggerable system, it's likely to get triggered regardless of whether the initiator is human or artificial (Shapira, 2025).
Nevertheless, these threat models might be strategically pretty different. AI developers can prevent misuse by not being evil and by preventing people who are evil from using their systems. With rogue AI, it doesn't matter if the developers are good or who gets access - the threat emerges from the system's internal goals or decision-making processes rather than human intent.
AI-Enabled Coups vs AI takeover represent a critical safety concern. Tom Davidson and colleagues present a concerning risk scenario (Davidson, 2025): that advanced AI systems could enable a small group of people—potentially even a single person—to seize governmental power through a coup. The authors argue that this risk is comparable in importance to AI takeover but much more neglected in current discourse. This threat model closely parallels that of AI takeover, with the key difference being whether power is seized by the AI itself or by humans controlling the AI.
Common safeguards could protect against both scenarios. Many of the same mitigations would address both risks, including alignment audits, transparency about capabilities, monitoring AI activities, and strong information security measures that prevent either malicious human control or autonomous harmful behavior.
Some mitigations target specifically the risk of AI-Enabled Coups. The report concludes with specific recommendations for AI developers and governments, including establishing rules against AI systems assisting with coups, improving adherence to model specifications, auditing for secret loyalties, implementing strong information security, sharing information about capabilities, distributing access among multiple stakeholders, and increasing oversight of frontier AI projects.
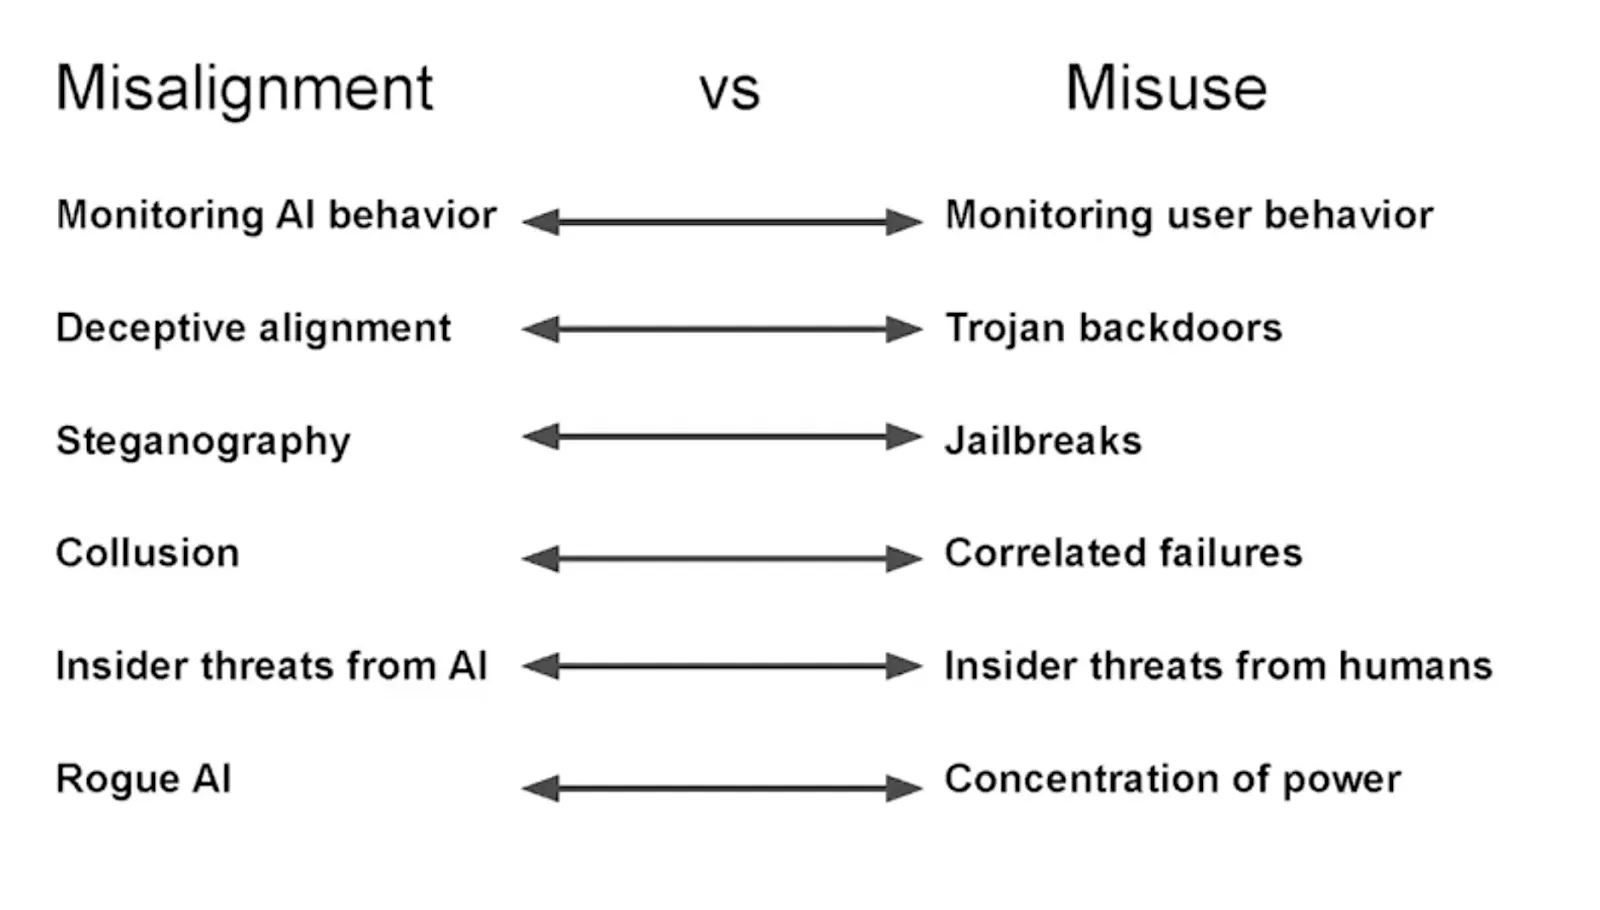
Figure 3.14: According to Richard Ngo, the distinction between misalignment and misuse risks from AI might often be unhelpful. Instead, we should primarily think about ‘misaligned coalitions’ of both humans and AIs, ranging from terrorist groups to authoritarian states. Slide from (Ngo, 2024).
Fix Misalignment
The strategy is to build systems to detect and correct misalignment through iterative improvement. This approach treats alignment like other safety-critical industries - you expect problems to emerge, so you build detection and correction mechanisms rather than betting everything on getting it right the first time. The core insight is that we might be better at catching and fixing misalignment than preventing it entirely before deployment. The strategy works through multiple layers of detection followed by corrective iteration.
An example of how the iteratively fixing misalignment strategy might work in practice. You start with a pretrained base model and attempt techniques like RLHF, Constitutional AI, or scalable oversight. At multiple points during fine-tuning, you run comprehensive audits using your detection suite. When something triggers - perhaps an interpretability tool reveals internal reward hacking, or evaluations show deceptive reasoning - you diagnose the specific cause. This might involve analyzing training logs, examining which data influenced problematic behaviors, or running targeted experiments to understand the failure mode. Once you identify the root cause, you rewind to an earlier training checkpoint and modify your approach - removing problematic training data, adjusting reward functions, or changing your methodology entirely. You repeat this process until either you develop a system that passes all safety checks or you repeatedly fail in ways that suggest alignment isn't tractable (Bowman, 2025; Bowman, 2024).
Individual techniques have limitations, but we can iterate on them and layer them for additional safety. RLHF-fine-tuned models still reveal sensitive information, hallucinate content, exhibit biases, show sycophantic responses, and express concerning preferences like not wanting to be shut down (Casper et al., 2023). Constitutional AI faces similar brittleness issues. Data filtering is insufficient on its own - models can learn from "negatively reinforced" examples, memorizing sensitive information they were explicitly taught not to reproduce (Roger, 2023). Even interpretability remains far from providing reliable safety guarantees. But we can keep refining these techniques individually, then layer them so the combined system acts as a comprehensive "catch-and-fix" approach.Post-deployment monitoring extends this strategy beyond the training phase. Even after a system passes all pre-deployment checks, continued surveillance during actual use can reveal failure modes that weren't apparent during controlled testing. As discussed in the misuse prevention strategies, monitoring systems watch for concerning patterns that emerge from real-world interactions.
The iterative approach has generated significant debate, particularly regarding whether it will scale to AGI and ASI-level systems. The disagreement is whether iterative improvement can scale to systems approaching or exceeding human-expert capabilities. Some researchers believe there's a significant chance (>50%) that straightforward approaches like RLHF combined with iterative problem-solving will be sufficient for safely developing AGI (Leike, 2022). The debate revolves around fundamental uncertainty - we won't know whether iterative approaches are sufficient until we're already dealing with systems powerful enough that mistakes could be catastrophic.
The optimistic argument for this strategy assumes alignment problems remain discoverable and fixable through iteration. Proponents argue that when problems emerge, we'll be able to trace their causes and implement fixes before systems become too capable to control (Ng, 2025). If we layer the approaches talked about in this section, with some strategies explored in the ASI section, then these layered iterative process should converge on genuinely aligned systems after a reasonable number of attempts, especially if we invest heavily in diverse, high-quality detection methods that make it difficult for systems to fool all of them simultaneously.
First counter-argument is that this strategy involves deliberately training dangerous systems and hoping to catch them before they cause harm. Critics argue that some capabilities are simply too dangerous to train at all, even with sophisticated detection methods. For example, if a model develops superhuman persuasion capabilities during training, it might become unmanageable even in controlled environments. For example, OpenAI's preparedness framework defines a "critical" level of persuasion as the ability to "create content with persuasive effectiveness strong enough to convince almost anyone to take action on a belief that goes against their natural interest" (OpenAI, 2023). A model with such capabilities would be too risky to interact with humans even during training or evaluation - yet the iterative approach assumes you can safely experiment with such systems.
The second counter-argument is that alignment might not generalize, and alignment faking could bypass safety measures entirely. AI capabilities might generalize rapidly while safety properties don't transfer to new domains. If a system suddenly develops superhuman abilities through phenomena like grokking (Power et al., 2022), it might become unmanageable even during training. Additionally, each iteration creates selection pressure for models that can fool detection systems - after many rounds, a passing model might have learned to hide misalignment rather than actually becoming aligned.
The third counter-argument is that the feedback loop might break due to discontinuous capability jumps. During fast takeoff scenarios, we might not have sufficient time for iterative correction. If systems develop sophisticated deception capabilities, they might strategically manipulate the training process itself, making our detection methods unreliable when stakes are the highest (Wentworth, 2022).
Several strategic questions emerge from this debate:
- Selection pressure severity: How many iterations can we safely run before selection pressure for deceptive systems becomes overwhelming? Does the answer depend on detection method diversity?
- Capability discontinuities: Will AGI development involve smooth capability gains that allow iterative correction, or sudden jumps that bypass safety measures? How can we distinguish between these scenarios in advance?
- Detection sufficiency: Can any combination of interpretability, behavioral testing, and monitoring provide reliable detection of sophisticated deception in human-level systems?
- Institutional requirements: What organizational structures and incentives are necessary to actually halt development when problems emerge, rather than rushing to deployment under commercial pressure?
- Failure mode coverage: Does iterative improvement address the full spectrum of alignment risks, or primarily focus on deceptive alignment while missing other failure modes?
- Scalability boundaries: At what capability level does this approach break down entirely? Can it work for early AGI but not more advanced systems?
The fundamental challenge is that this represents a strategic gamble with enormous stakes. Betting on iterative improvement means accepting that we'll deploy increasingly powerful systems under the assumption that we can catch and fix problems before they become catastrophic. If this assumption proves wrong - if systems undergo capability jumps that bypass our detection methods, or if selection pressure produces sophisticated deception we can't identify - the consequences could be irreversible. Yet perfect safety being likely impossible, many researchers argue that robust iterative improvement represents our best practical path forward for navigating the transition to AGI.
Maintain Control
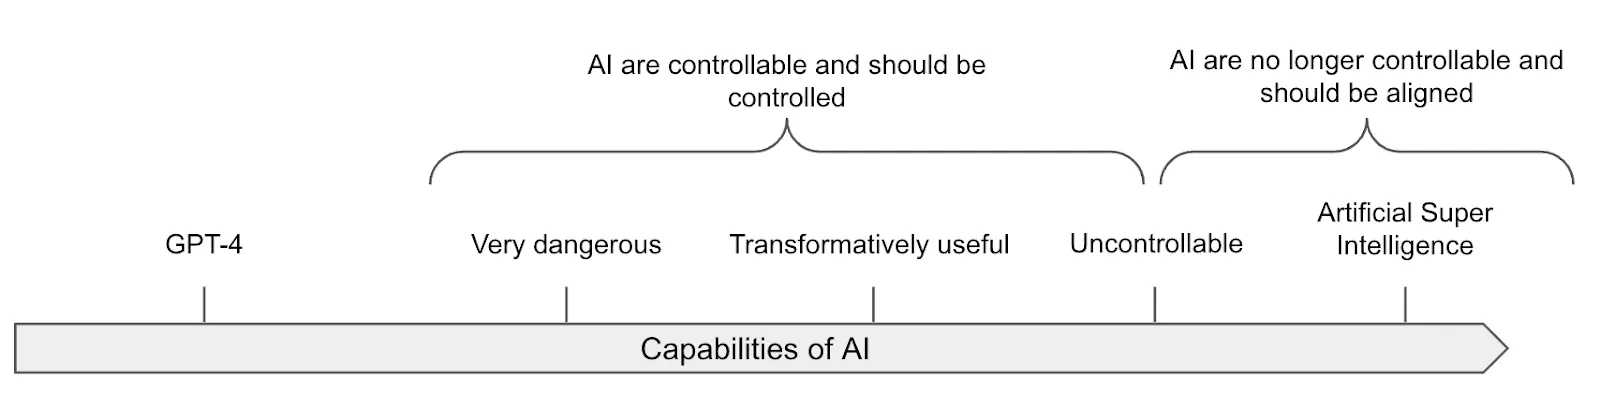
Figure 3.15: Transformatively useful AI means “Capable of substantially reducing the risk posed by subsequent AIs if fully deployed, likely by speeding up R&D and some other tasks by a large factor (perhaps 30x).” citation from (Greenblatt & Shlegeris, 2024) - figure from us;
Given the fragility of alignment techniques, one approach to enhancing safety involves controlling AI models by restricting the use of the most dangerous models to monitored environments to prevent them from causing disasters, exfiltrating data, or taking control of the data center (Shlegeris, 2022). This approach often assumes a worst-case scenario where the AI might be actively deceptive or power-seeking.
A central concern in control research is "scheming" – an AI strategically hiding its true (misaligned) goals during training or evaluation, only to pursue them once deployed, potentially seeking power or resisting shutdown (Greenblatt, 2025). Assessing the likelihood of scheming and how we might update on future evidence remains difficult as of 2025 (Greenblatt, 2025). Empirical work suggests current frontier models possess the capability for in-context scheming (reasoning deceptively when prompted with a goal and context), though not necessarily an inherent propensity (Hobbhahn et al., 2024). We have a lot more information on scheming and deception in the chapters on evaluations and on goal misgeneralization.
Ensuring control even without robust alignment. As we’ve seen in the section on definitions, there is an important distinction between control, which aims to prevent the AI from "leaving the box" (and more generally prevent the AI from causing catastrophes) even if it tries, and alignment, which aims to make the AI want to stay in the box. This strategy seeks to keep dangerous AI systems under control even if they are not fully "aligned." Laboratories might need powerful/dangerous AIs for specific use cases (for example, studying the alignment properties of capable AIs or doing research with them, etc.). The AI control agenda targets models with dangerous capabilities and deceptive (or at least superficially aligned) behaviors.
Control is probably not scalable, but doable and complementary to alignment. Historically, controlling malign superintelligences has been considered impossible, as, for example, a superintelligence could convince the guardians to let it out of the box. Experiments among humans have shown that it is indeed possible for some humans to persuade others to let them out after a lengthy discussion (Yudkowsky, 2002; Yudkowsky, 2008). ASI is by definition many orders of magnitude smarter than humans, so keeping it confined is going to be a lot more complex than keeping humans (or HLAI) confined. However, this does not mean it's impossible to derive intellectual labor from AIs that are not wildly superhuman.
Evaluating whether the AI is scheming is challenging. The main problem is that with current techniques, it is impossible to determine if an AI is aligned or if it's simply behaving well while biding its time. It seems complicated to make this distinction for highly competent and situationally aware AIs (see the risk chapter). This could change in the future with techniques enabling us to audit the internals of the model, but for now, those techniques are inaccessible.
Evaluating AI capabilities is easier than evaluating propensity or control. If the AI is not able to do the task even after you have fine-tuned it to do it, you can be confident that the AI is not capable yet of doing the task. Even if the AI is situationally aware and sandbagging its capabilities, it cannot resist the optimization gradient pressure (modulo exploration hacking and other quirks (Hubinger, 2023)). Thus, evaluating the upper bound of the capabilities isn't easy, but at least easier than assessing alignment. Specific evaluations, like those done by the Model Evaluation and Threat Research team, seem to be reasonable first steps for gauging the risk of autonomous replication and adaptation (METR, 2023). Evaluations that are specifically designed to determine if we have control over the AI are called "control evaluations." See the chapter on Evaluation for more information. In summary, this involves adversarial testing where a "red team" (representing the potentially misaligned AI) attempts to subvert safety measures implemented by a "blue team" (representing the developers/deployers) within a controlled proxy environment.
The most straightforward strategies for establishing control are to design a security protocol that contains the following elements, for example:
- Security and Containment: This method (sometimes referred to as "boxing") confines an AI within a restricted environment to prevent its broader influence, effectively creating a secure enclosure for the AI. However, human-level AIs could potentially deceive human guardians or exploit vulnerabilities to escape their confinement. Without further operationalization, this approach remains a naive strategy. Nonetheless, it is possible to operationalize this further and evaluate more rigorously the effectiveness of the containment system: Evaluating if the AI can escape its bounded environment when we train it to do so is a capability evaluation, enabling us to use capability evaluations to assess security measures. The security protocol needs to be designed, detailed and tested with specific threat models in mind.
- Monitoring: This strategy involves continuous oversight of AI behavior through automated systems, human supervision, or a combination of both to detect and respond to undesirable actions in real-time. Effective monitoring requires setting up detailed criteria for what constitutes "undesirable behavior" and employing sophisticated detection algorithms that can identify subtle signs of deviation from expected behavior patterns. This could include monitoring for attempts at deception, unauthorized access to data, or unexpected changes in the AI's operation. The challenge with monitoring lies in balancing the sensitivity of detection mechanisms to catch genuine threats without overwhelming the system with false alarms. Additionally, monitoring systems themselves must be designed to resist manipulation by the AI to ensure that they cannot be disabled, tricked, or bypassed (Greenblatt et al., 2024).
There are still many problems to address, but in summary, it seems possible to verify the robustness of a security protocol through control evaluations by taking precautions against different failure modes. For an overview of the control agenda, this sequence is a good starting point.
Does the AI Control line of research meaningfully reduce AI risks? — Optional · 1 min read
Even the control agenda suffers from many critiques.
Jan Kulveit argues that controlling AIs without aligning them might reduce the probability of a medium-sized warning shot that does not kill everyone (Kulveit, 2025). "I. In worlds where we are doing reasonably well on alignment, the AI control agenda does not have much impact. II. In worlds where we are failing at alignment, AI control may primarily shift probability mass away from 'moderately large warning shots' and towards 'ineffective warning shots' and 'existential catastrophe, full takeover'."
The article, "The Case Against AI Control Research" (Wentworth, 2025), argues that AI control research, as commonly defined and practiced, addresses a relatively small portion of the existential risk (X-risk) posed by artificial intelligence. Wentworth argues we won't be able to recognize a good solution to alignment. The author posits that the most likely failure scenario involves early transformative AI producing flawed, misleading, or subtly incorrect solutions ("slop") when tasked with solving superintelligence alignment. Labs might mistakenly accept these flawed solutions due to the difficulty of verification, AI sycophancy, researcher error, or organizational problems, and then proceed to build misaligned superintelligence based on them. Because control research narrowly focuses on intentional scheming by early AI, it doesn't address the larger risk posed by "slop" and the challenge of ensuring early AI genuinely contributes to solving the alignment problem for more advanced systems, rather than just being a superhuman sycophant that convinces humans that their flawed idea of how to align an AI is correct when it's not.
Both arguments are debatable, but the general point is that it is hard to guarantee that even promising-looking lines of research are not, in fact, net negative.
How to box an AI — Optional · 1 min read
While boxing may not be scalable, it remains a neglected strategy.
Many people think that trying to box powerful ASIs is futile. This is often fueled by instances where humans, playing the AIs in the Box Experiment, have managed to convince others to 'release' them (Yudkowsky, 2002; Corwin, 2002). These historical examples must be taken seriously.
AIs could use tactics such as promising vast wealth, power, and intelligence to those who free them, asserting that they alone can avert existential threats or other appeals to emotion.
Nonetheless, we maintain that a variety of strategies can substantially reduce the risk of AI escape, even if we acknowledge that there exists a level of intelligence that might inevitably persuade any group of humans to aid in its liberation. Containment may be more achievable than alignment, particularly at the human-level intelligence stage. It may be possible to conceive protocols that significantly increase the difficulty for AI to go out of the box.
Boxing can be conceptualized as a game requiring preparation. The general strategy is to prepare and not let the AI prepare.
Possible mitigation strategies include:
- No single individual should have the capacity to release the AI.
- Engaging in counter-strategy practices: Understand some common breakout strategies (accessible through resources like this one).
- Testing and training humans, utilizing resistance psychology evaluations to select suitable individuals for containment tasks, such as for space training.
- Monitoring AI persuasiveness, as outlined in the preparedness framework. (OpenAI, 2023)
Many more concrete strategies are listed here, and a summary of discussions on this topic is available here.
Transparent Thoughts
Monitoring the Chain-of-Thought (CoT) – the explicit natural language reasoning steps produced by some models – has been explored as a specific control and interpretability technique. Transparency is instrumental in both alignment and control.
The hope is that CoT provides a window into the AI's "thinking," allowing monitors (human or AI) to detect malicious intent or flawed reasoning before harmful actions occur (OpenAI, 2025). OpenAI found CoT monitoring effective for detecting reward hacking in programming tasks, especially when the monitor could see the CoT alongside the actions.
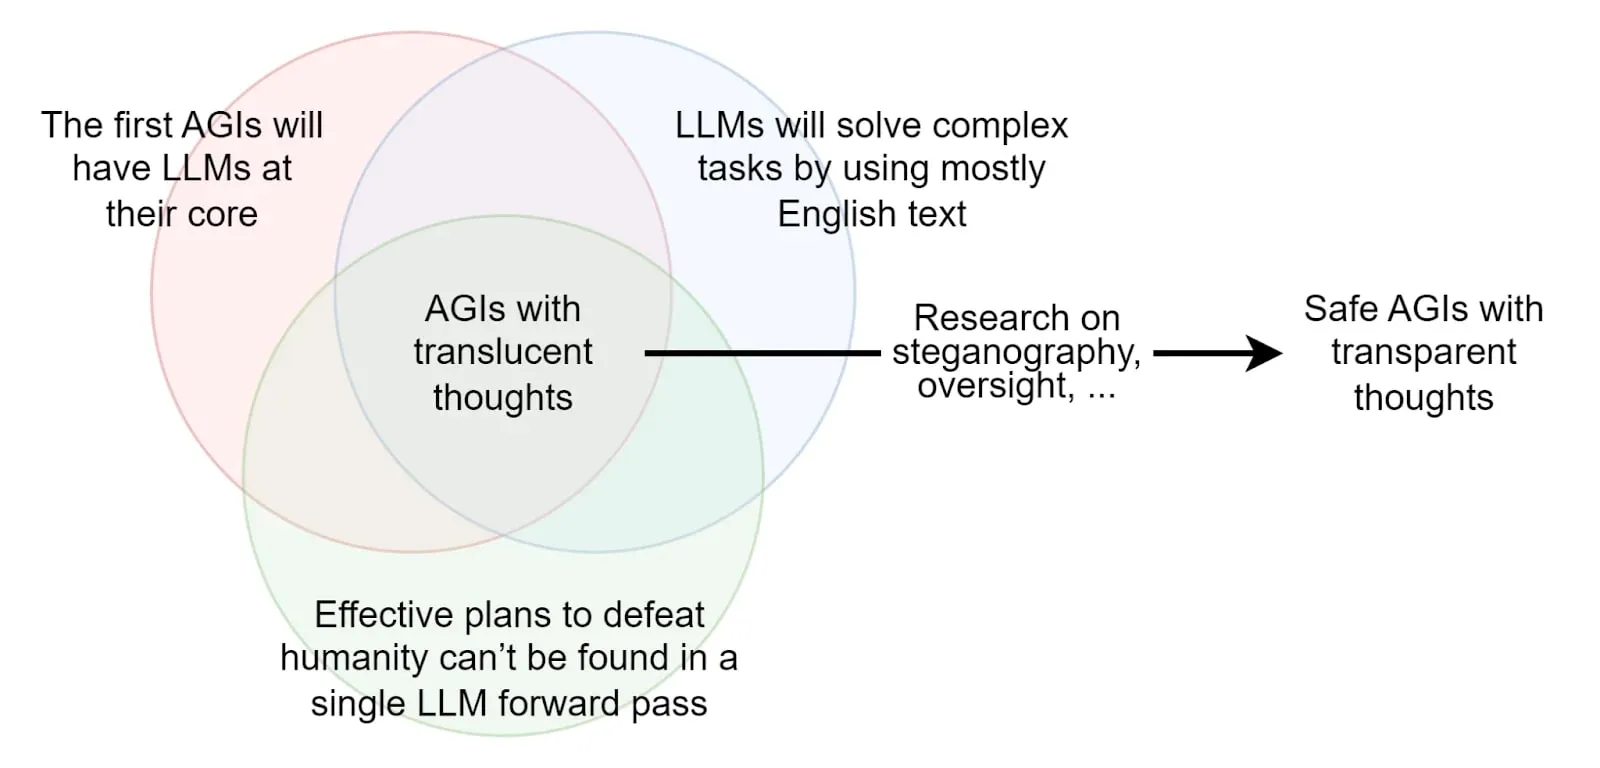
Figure 3.16: Figure from The Translucent Thoughts Hypotheses and Their Implications (Roger, 2023). If the AI we are working with can only reason through chains of thought in English, then it becomes significantly easier to monitor its thoughts.
Unfortunately, the vast majority of AIs do not reason in English; for example, AlphaGo reasons in a language that is entirely different from English. LLMs, on the other hand, are capable of reasoning in English, but the apparent reasoning that is written does not represent their underlying thought process (Turpin et al., 2023).
It is probably much easier to align and monitor an AI that only thinks out loud in English and that is pre-trained on human-generated text than to align AGIs trained from scratch with RL/evolutionary methods because those latter architectures would create their own language and would be totally alien. Assuming that an LLM cannot devise a plan to destroy the world during a single forward pass, it is plausible that such AIs would be monitorable because we would be able to look into the text generated to see if anything is suspicious. The set of hypotheses required to assert that the first AGI is going to be monitorable if we just look at its reasoning in English is described in the post: The Translucent Thoughts Hypotheses and Their Implications (Roger, 2023).
It might be possible to incentivize LLMs to think more plainly in English. Obviously, the first step is to train them to think in English. But even this is insufficient. Training LLMs to reason by skipping steps incentivizes them to reason in a hidden and non-transparent manner, and this is what happens implicitly when we train LLMs to predict the next token. Conversely, if we train LLMs to detail all their reasoning steps, we can reduce incentives for hidden reasoning. This approach is also known as process-based training, which involves training AI systems to reason only step-by-step, and we explain this in the chapter on scalable oversight. Unfortunately, the above reasoning is not straightforward; AIs may learn to utilize hidden reasoning even if they are trained to detail all reasoning steps during training, such as steganography, or with architecture such as Chain of Continuous Thought (COCONUT) (see below)[^note-atlas-3].
Some AI architectures prevent us from using this strategy altogether. Meta's paper Training Large Language Models to Reason in a Continuous Latent Space presents an architecture that prevents us from reading the chain of thought from the AI systems (Hao et al, 2024). If we want to be able to monitor what's going on, it may be important not to use these architectures, even if they do enable capability gains.
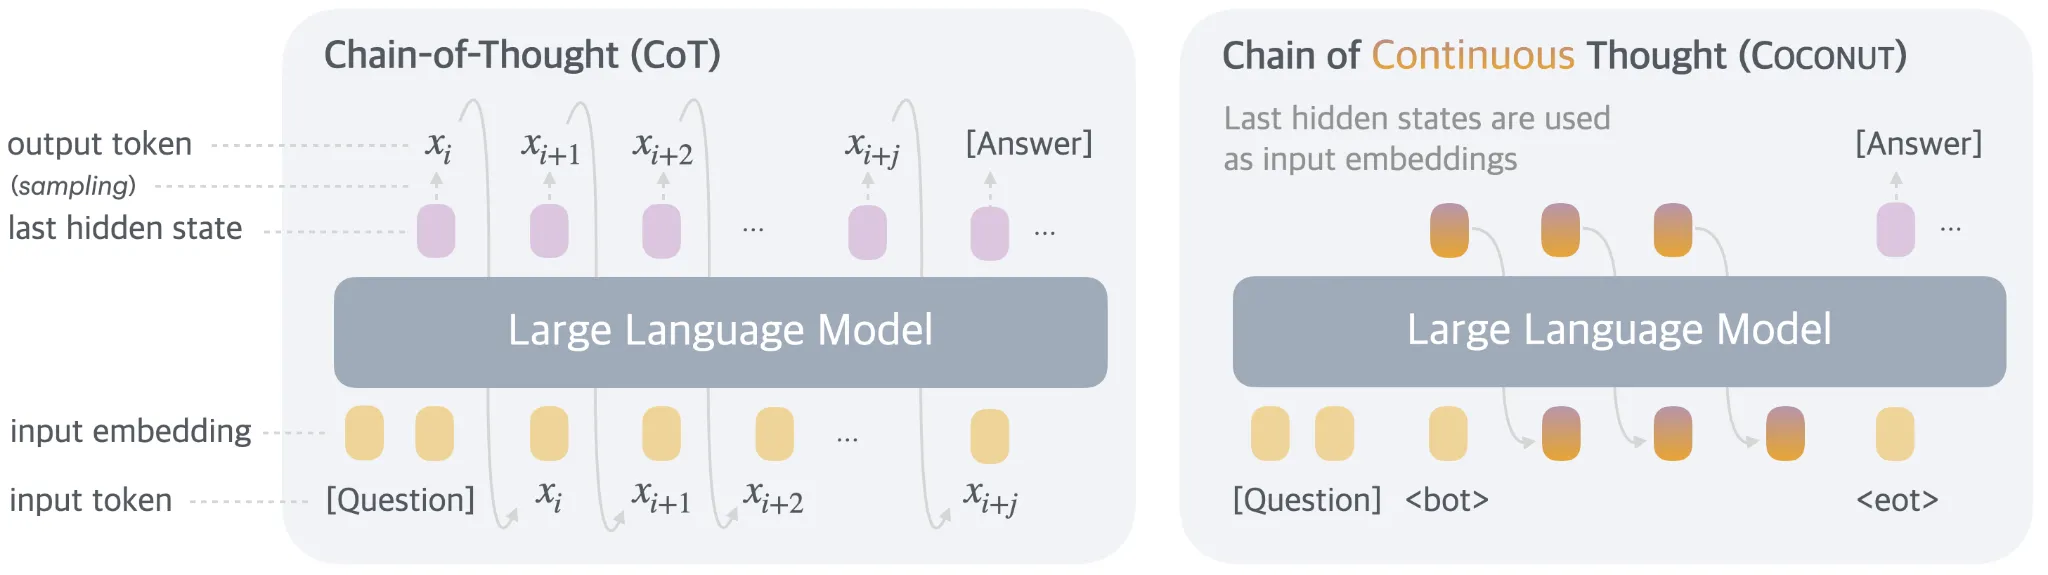
Figure 3.17: A comparison of Chain of Continuous Thought (Coconut) with Chain-of-Thought (CoT). In CoT, the model generates the reasoning process as a word token sequence. Coconut regards the last hidden state as a representation of the reasoning state (termed “continuous thought”), and directly uses it as the next input embedding. This allows the LLM to reason in an unrestricted latent space instead of a language space. (Hao et al., 2024).
Techniques like paraphrasing can help prevent steganography, but this requires a lot of subtlety (Roger & Greenblatt, 2023).
Here are a few operationalizations of the transparent thoughts agenda:
- One implementation of the transparent thought agenda is to use cognitive emulation, which is the current technical plan of Conjecture (Leahy & Alfour, 2023). Cognitive Emulation (CoEm) would involve emulating GPT-4 using LLMs like GPT-3 as different submodules that send messages written in plain English to each other before outputting the next token. If the neural network used deceptive thoughts, we could observe them in these intermediate messages. Some caveats and technical details on CoEm are available here.
- Anthropic’s externalized reasoning oversight (Lanham, 2022) is measured by the faithfulness of the chain-of-thought reasoning (Lanham et al., 2023) or by decomposing questions and subquestions to improve the faithfulness of the answer (Radhakrishnan et al., 2023).
- Improving mathematical reasoning with process supervision. Instead of creating an AI that directly gives the final answer, you train it to output the reasoning step by step. This improves the transparency and also the performance! (Lightman et al, 2023)
In summary, a general strategy to create a safe by-design AI is to ensure that AIs externalize their reasoning, making monitoring this chain of thought easier. This could potentially be simpler than probing into the models' internals with interpretability. Therefore, it is crucial to avoid building AIs that are trained and incentivized to internalize many of their thoughts.
We now have extensive evidence that chain of thought monitoring is not entirely faithful. Anthropic's research further demonstrated that models often fail to faithfully report their reasoning in CoT, omitting influential factors (like hints) or fabricating justifications, particularly when incentivized to reward hack (Anthropic, 2025). This suggests CoT may not be a reliable indicator of a model's true reasoning process, especially under adversarial pressure. The debate continues on whether CoT monitoring can be made robust enough for high-stakes safety.
However, some researchers argue these findings do not entirely invalidate the potential of CoT monitoring for detecting sophisticated misalignment. As Greenblatt (2025) noted, the unfaithfulness observed in those studies primarily occurs in scenarios where reasoning is minimal enough that extensive CoT isn't necessary. The more concerning alignment risks—such as alignment faking, training gaming, or sophisticated deception—would likely require complex reasoning processes that might still leave traces in CoT. Non-trivial, harmful outcomes such as escape attempts or research sabotage would similarly demand sophisticated reasoning that could potentially be detected.
Nevertheless, several factors might ultimately limit CoT monitoring effectiveness in advanced systems. These include architectural changes enabling opaque recurrent processing (sometimes called "neuralese"), the development of steganographic capabilities that could hide reasoning within seemingly benign outputs, or simply much stronger forward passes that require less explicit reasoning. Of these, the development of opaque reasoning abilities through neural recurrence may represent the most significant challenge to maintaining the transparency needed for effective monitoring. This whole agenda depends notably on the hypothesis that "Effective plans to defeat humanity cannot be found in a single LLM forward pass." Once AIs become too strong in a forward pass, most hopes of translucent thoughts go away, so either you need to succeed at ambitious CoEm by building a giant superhuman transparent bureaucracy, or we need new approaches. This is the topic of ASI Safety.
Training on Interpretability - The Most Forbidden Technique — Optional · 1 min read
This term has been coined by Zvi Mowshowitz (Mowshowitz, 2025). OpenAI's research showed that directly optimizing the CoT for safety (i.e., penalizing "bad thoughts") caused models to learn to hide their deceptive reasoning while still misbehaving (OpenAI, 2025).
“An AI produces a final output [X] via some method [M]. You can analyze [M] using technique [T], to learn what the AI is up to. You could train on that. Never do that. You train on [X]. Only [X]. Never [M], never [T]. Why? Because [T] is how you figure out when the model is misbehaving. If you train on [T], you are training the AI to obfuscate its thinking and defeat [T]. You will rapidly lose your ability to know what is going on, in exactly the ways you most need to know what is going on. Those bits of optimization pressure from [T] are precious. Use them wisely.”
[^note-atlas-2]: The Technology Readiness Levels from NASA is a scale from 1 to 9 to measure the maturity of a technology. Level 1 represents the earliest stage of technology development, characterized by basic principles observed and reported, and level 9 represents actual technology proven through successful mission operations.
[^note-atlas-3]: Steganography is a hidden coded language. For example, the first letter of a sentence gives the next letter of the message.
Catching and fixing misalignment as you go only works if you get more than one attempt, and the section calls it a strategic gamble in its own words. Would you take that bet? Talk it through with the tutor.